

Overview
A Custom Transform in Condense is a fully code-based processing component that you build in the built-in IDE, version-control through Git, and deploy into a workspace pipeline. Unlike prebuilt transforms, custom transforms let you implement domain-specific logic, advanced event processing, and cross-event correlation in any programming language supported by the Condense IDE. Once built and published, a custom transform appears alongside prebuilt transforms in the pipeline editor and is ready to deploy.Custom transforms are created through Applications in Condense — the built-in development environment where you write, build, and publish your logic before it becomes deployable.
What You Can Do with a Custom Transform
- Implement domain-specific rules, enrichment, or routing not covered by prebuilt options.
- Write logic in any programming language supported in the Condense IDE.
- Perform advanced processing, cross-event correlation, or domain-specific analytics.
- Version-control all logic through Git, with immutable published versions.
- Roll back to earlier versions at any time from the pipeline editor.
Custom Transform Lifecycle
Every custom transform follows this lifecycle: Create → Develop → Build → Publish → Deploy → Update/Rollback → DeleteStep 1 - Create an Application
Who can create: Workspace Admins, Maintainers, Developers
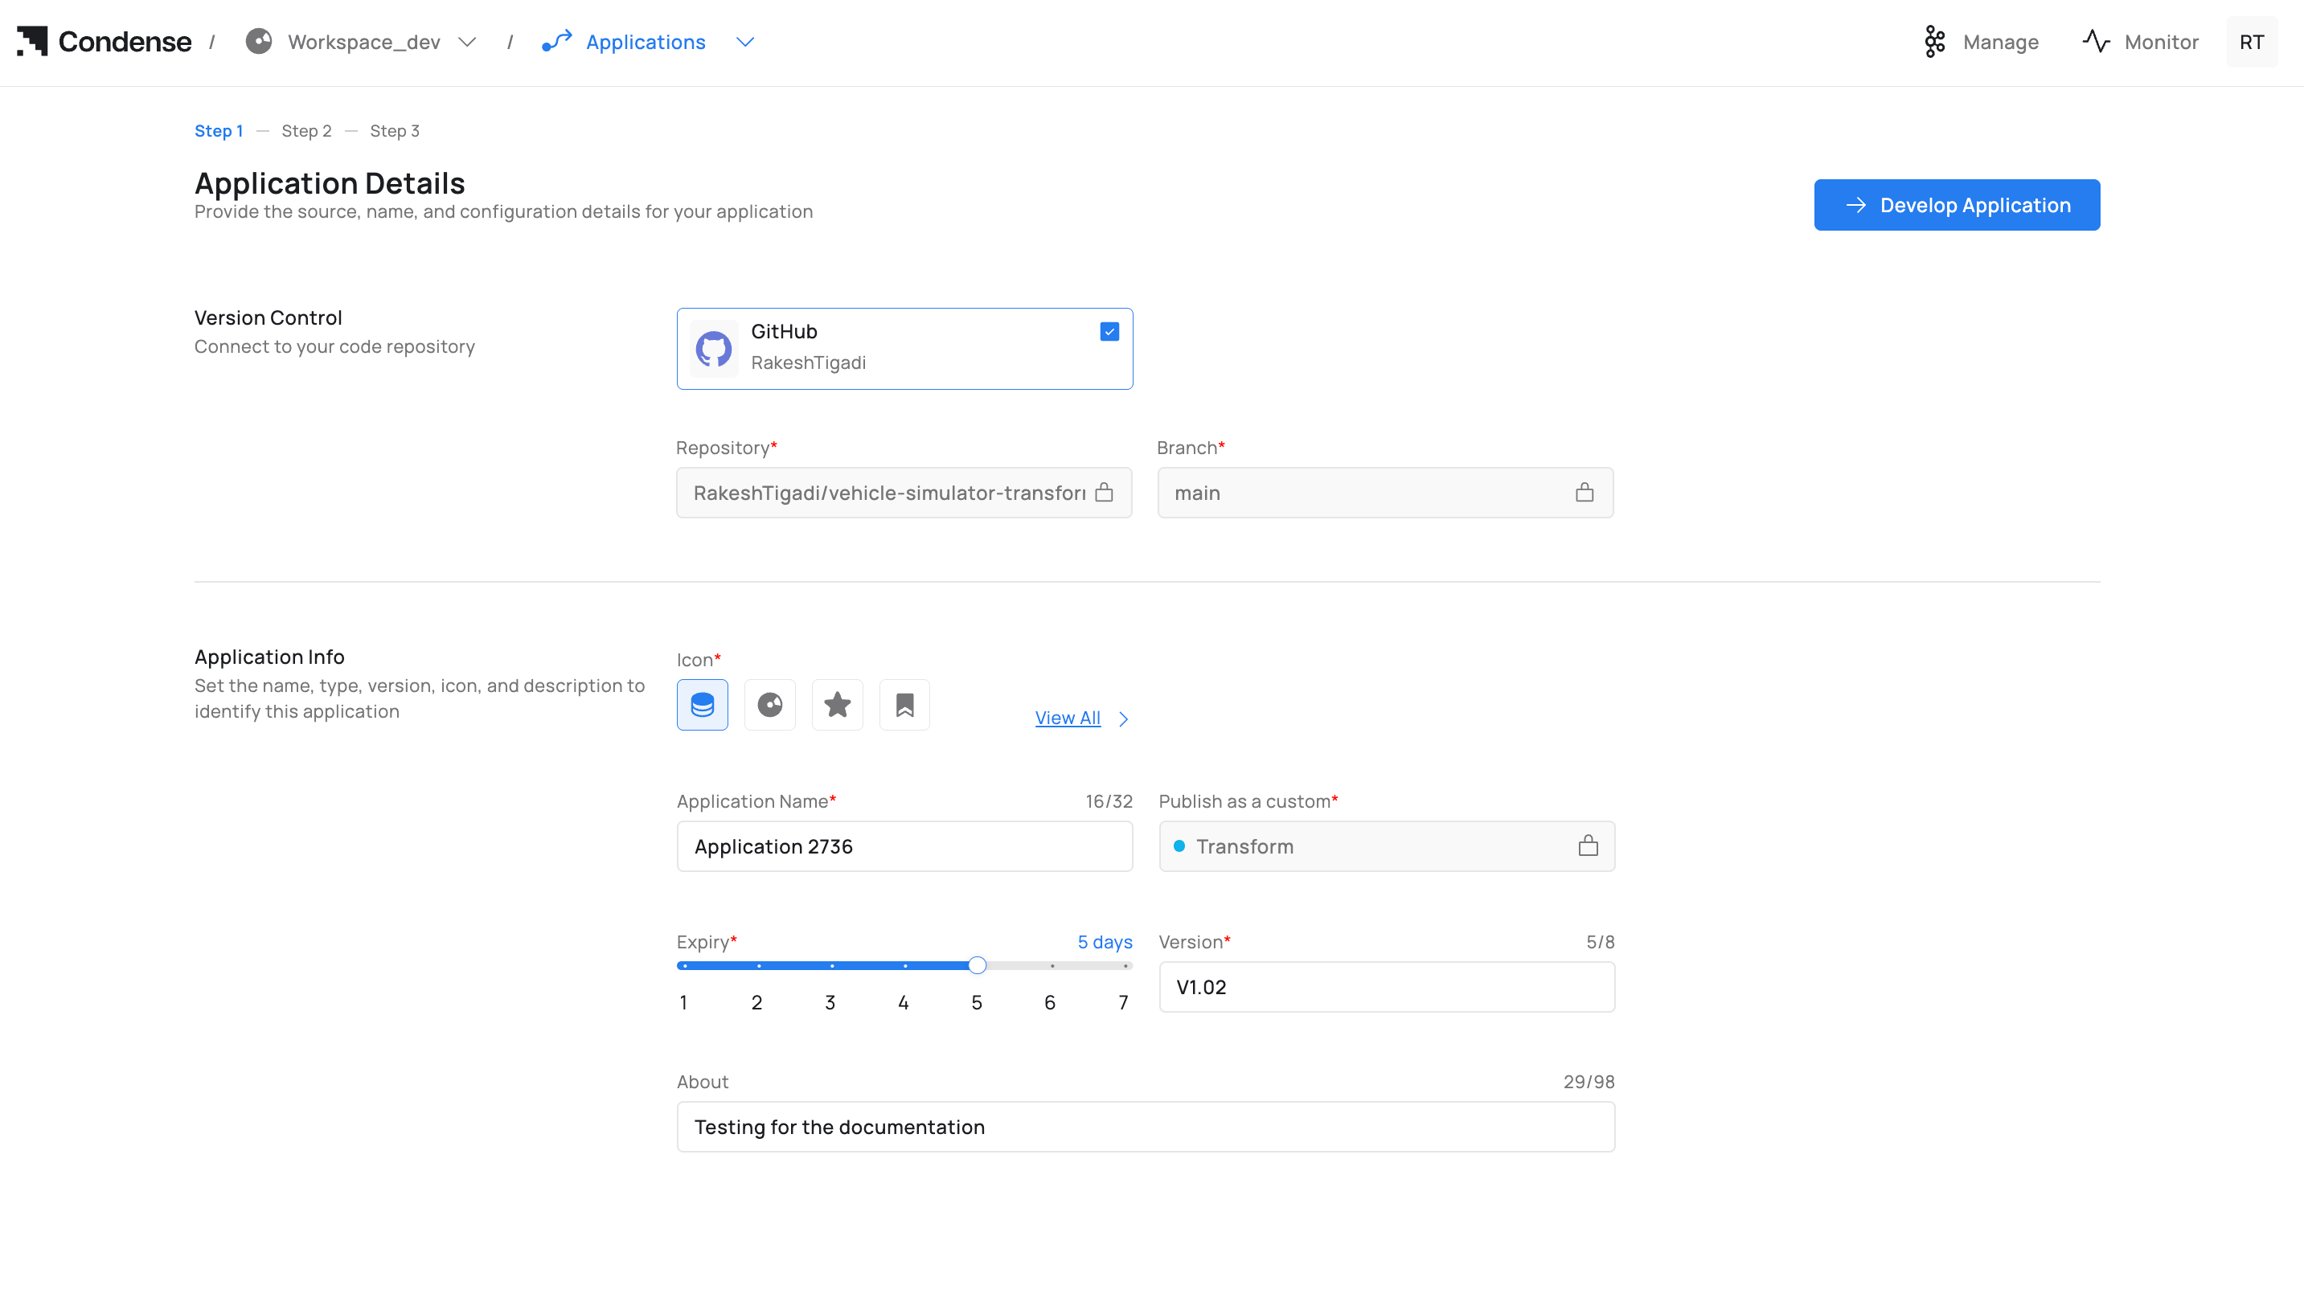
- Go to Applications in your workspace → click Create Application.
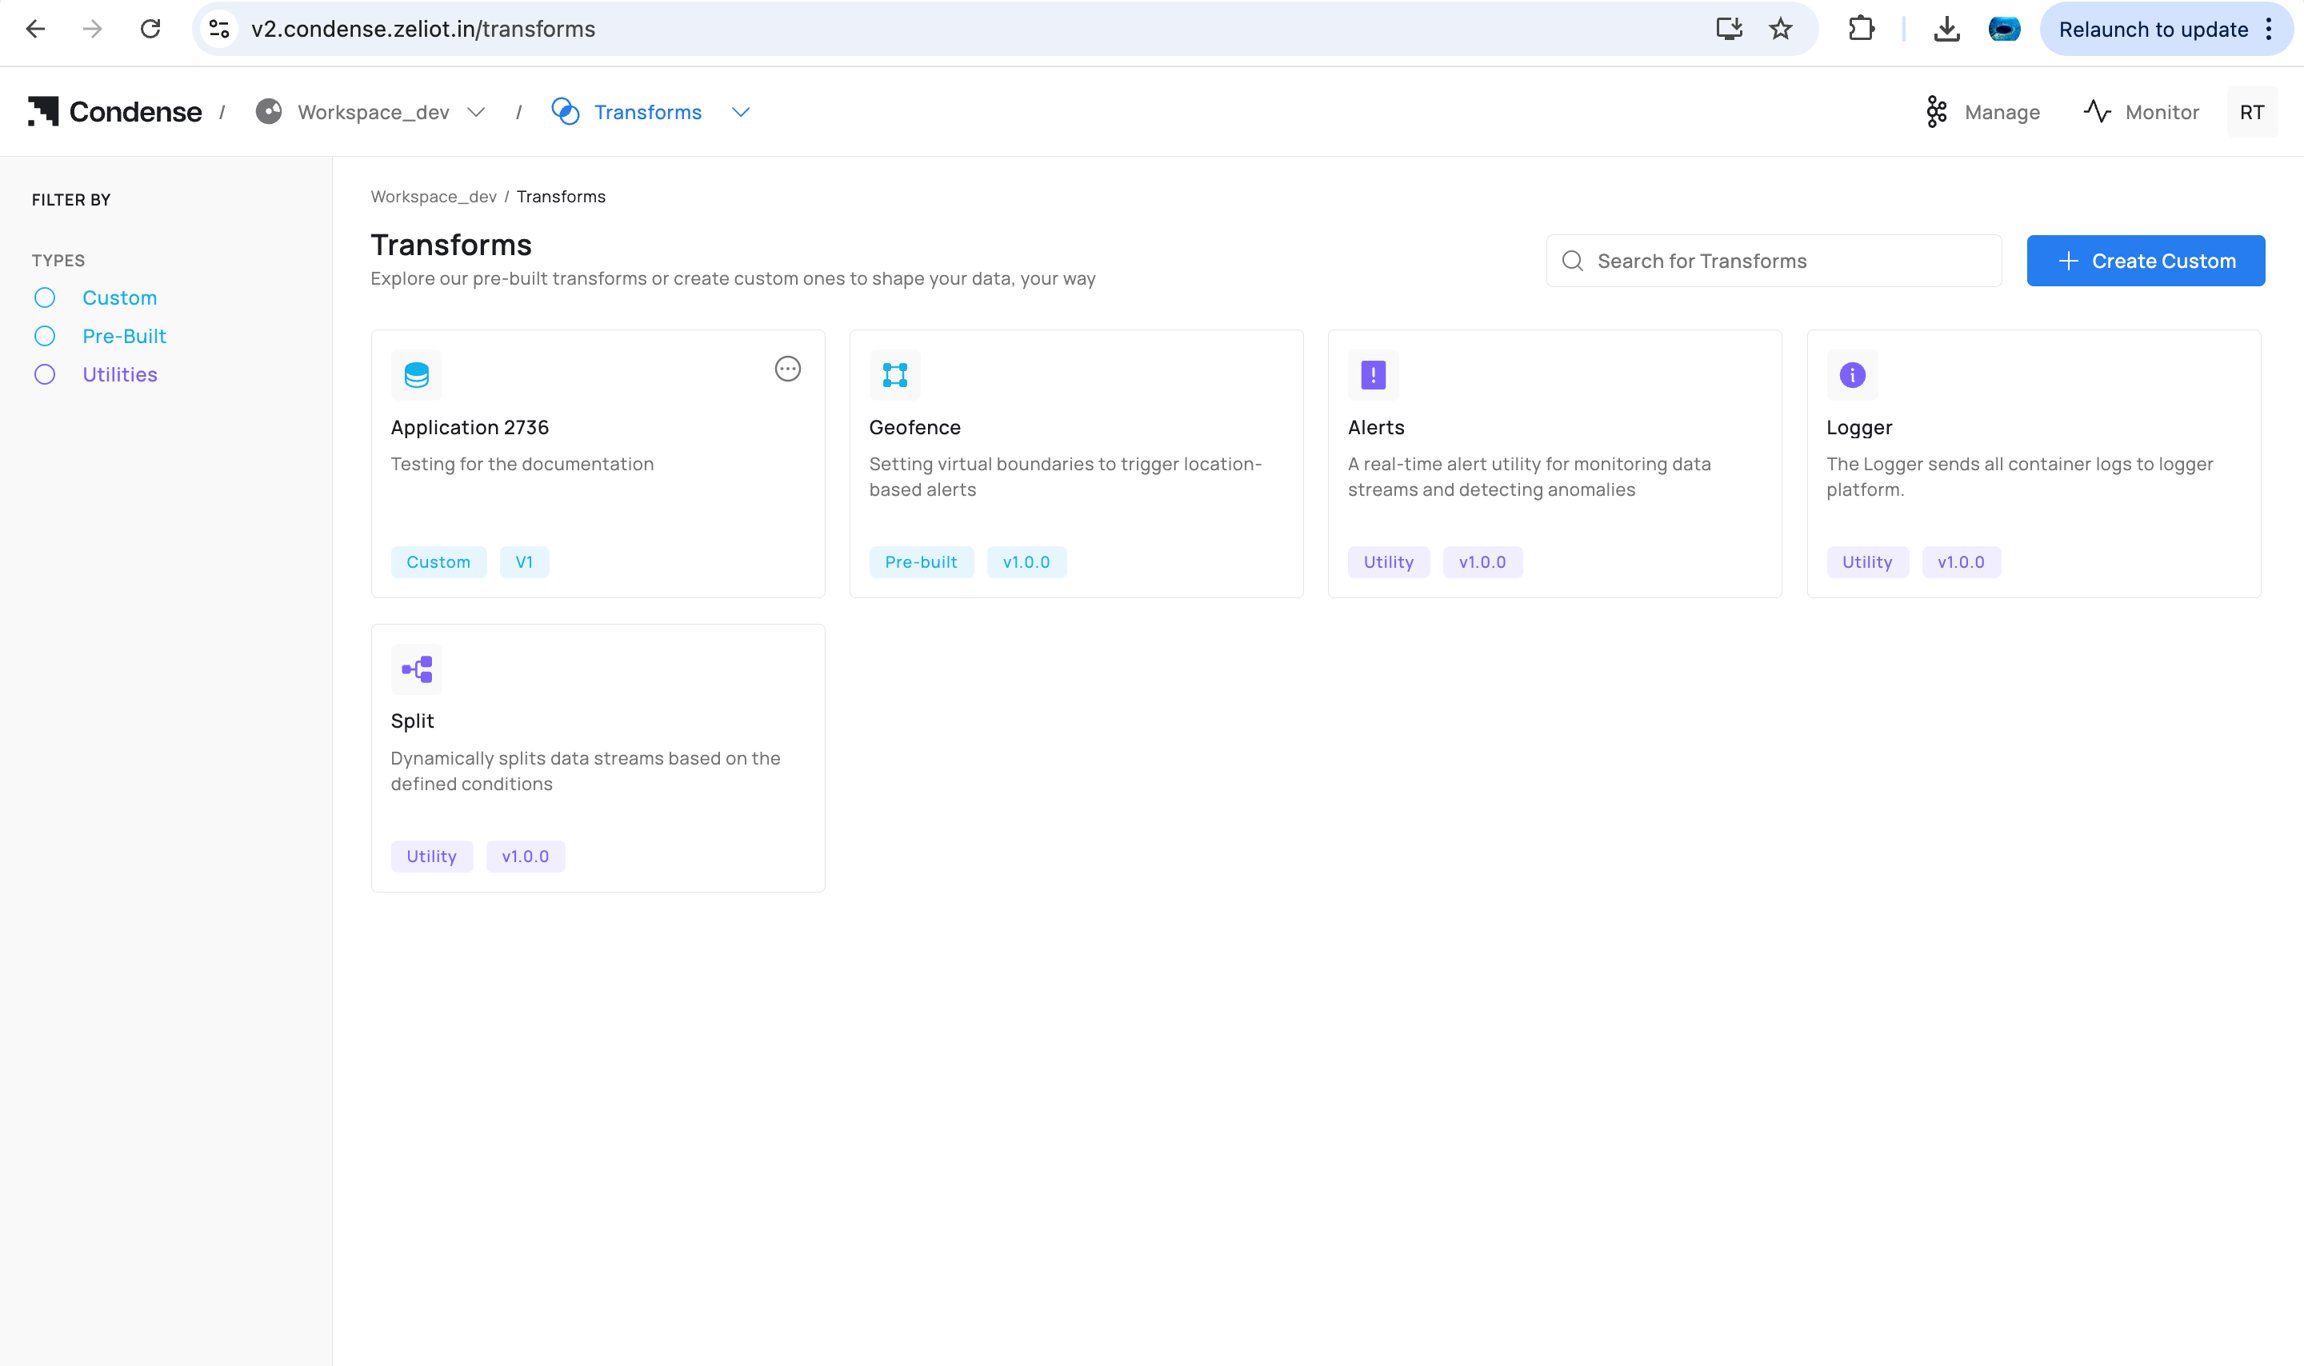
Create Application screen
- Version Control: Connect a Git provider (GitHub / GitLab / Bitbucket), then select your Repository and Branch.
- Application Info: Fill in the following fields:
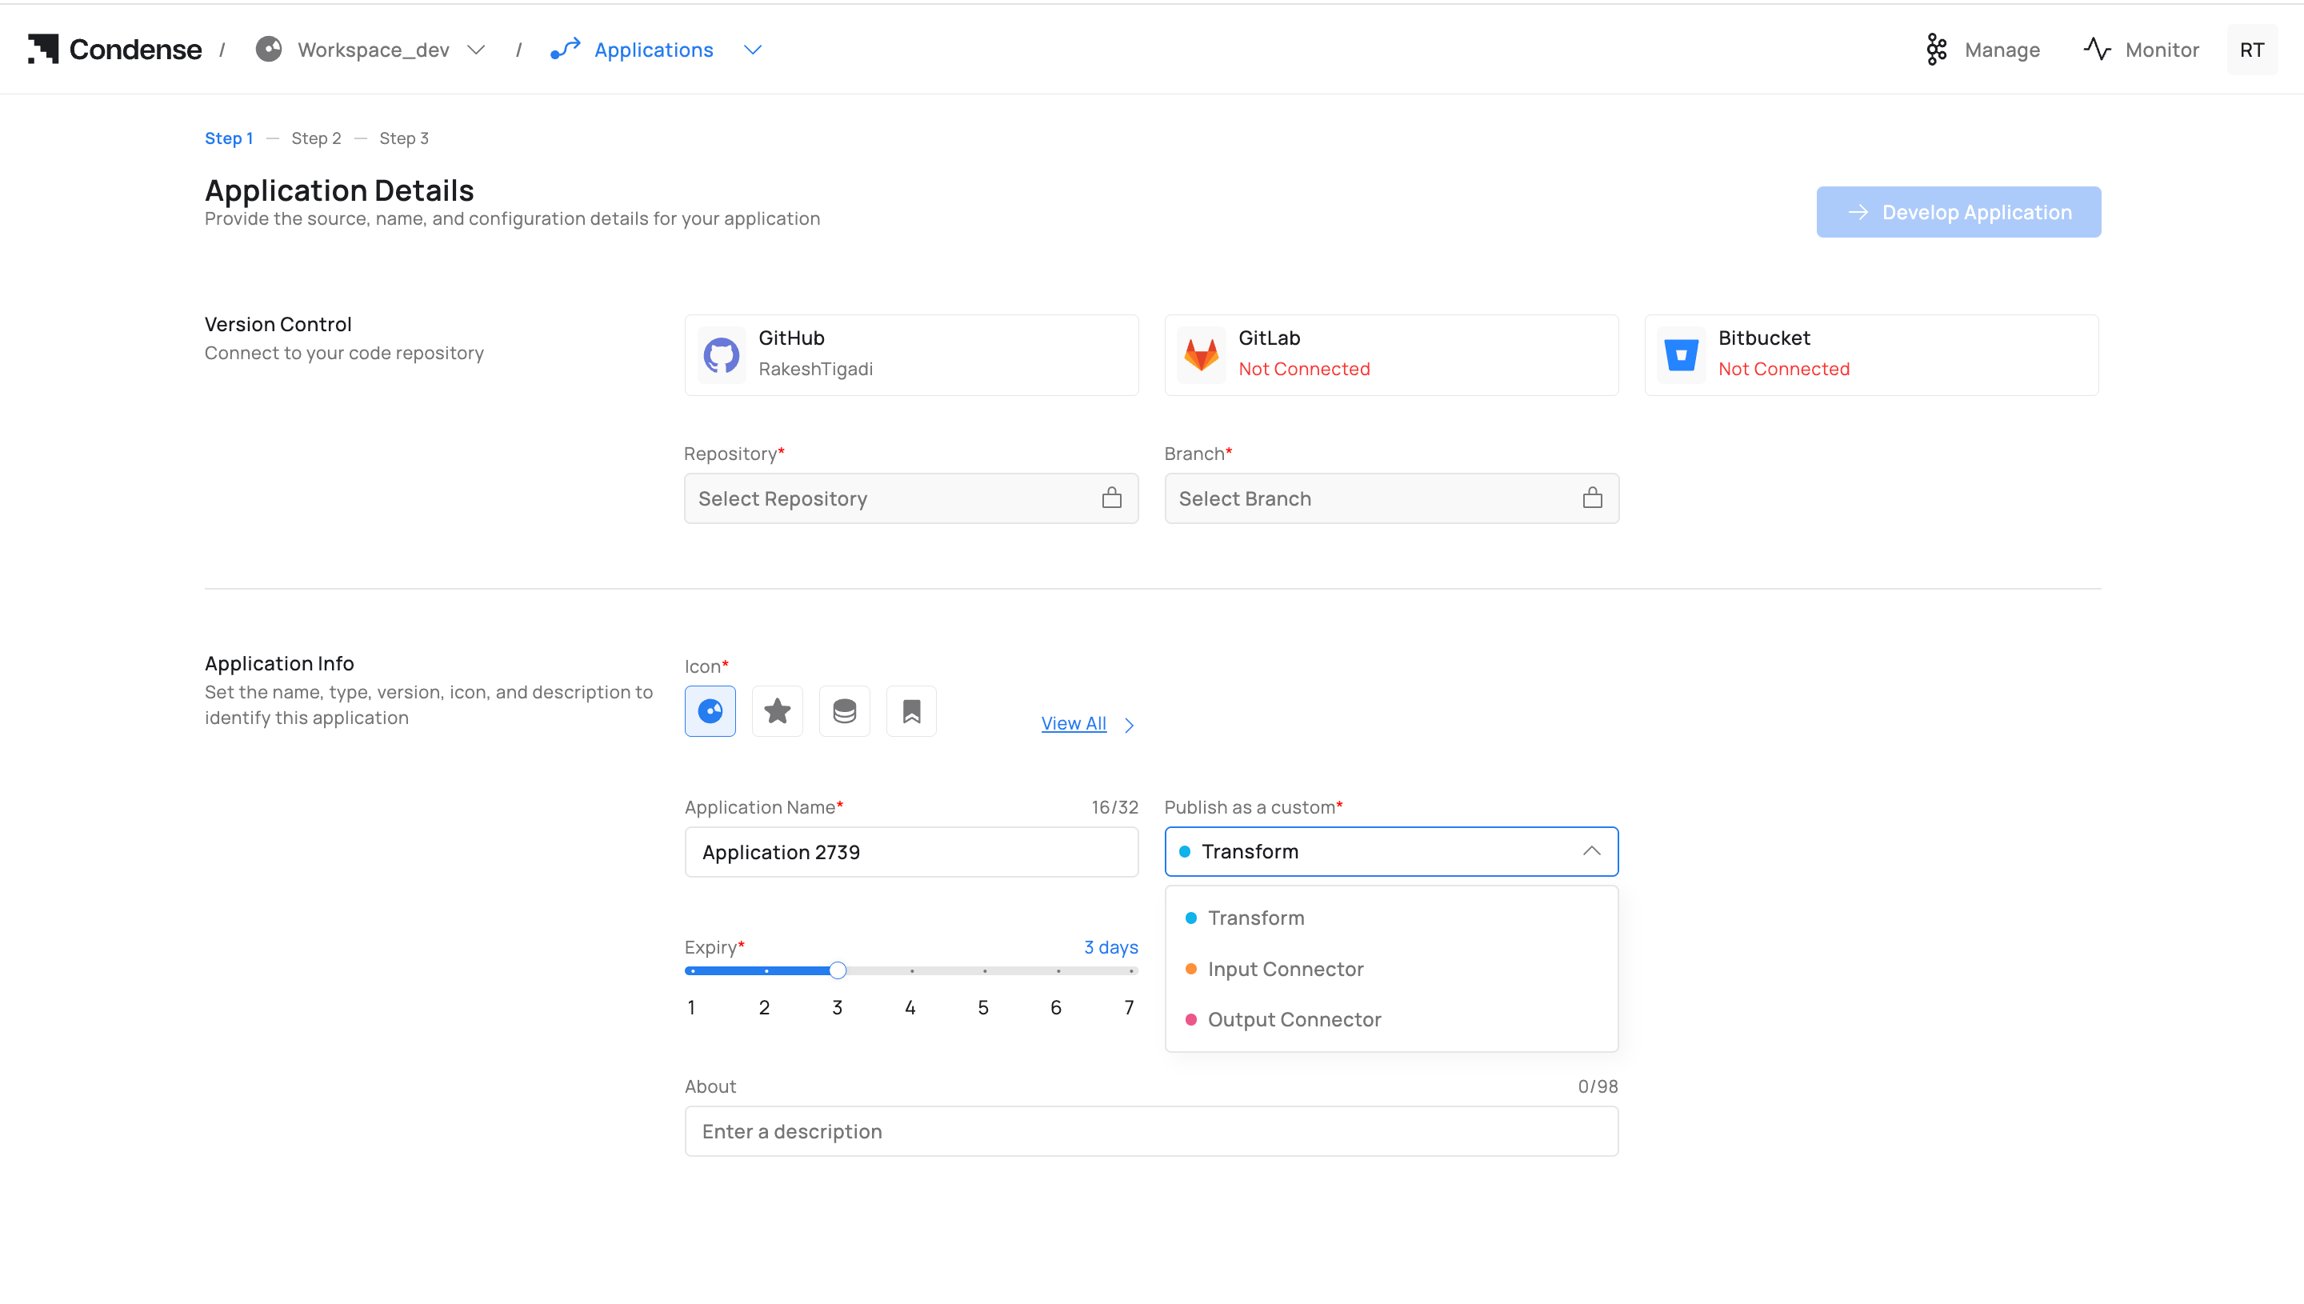
Application Info Fields
- Click Develop Application to open the IDE.
Step 2 - Develop in the IDE
Who can edit drafts: Admins, Maintainers, Developers
In the IDE, you can:
- Navigate and edit code via File Explorer and Code Editor.
- Configure ENVs (environment variables) for build/runtime.
- Optionally enable Expose HTTP(s) Server or Expose TCP Server for local testing.
- Validate topic flow with Publish and Subscribe testers.
- Commit and push to the connected Git repository.
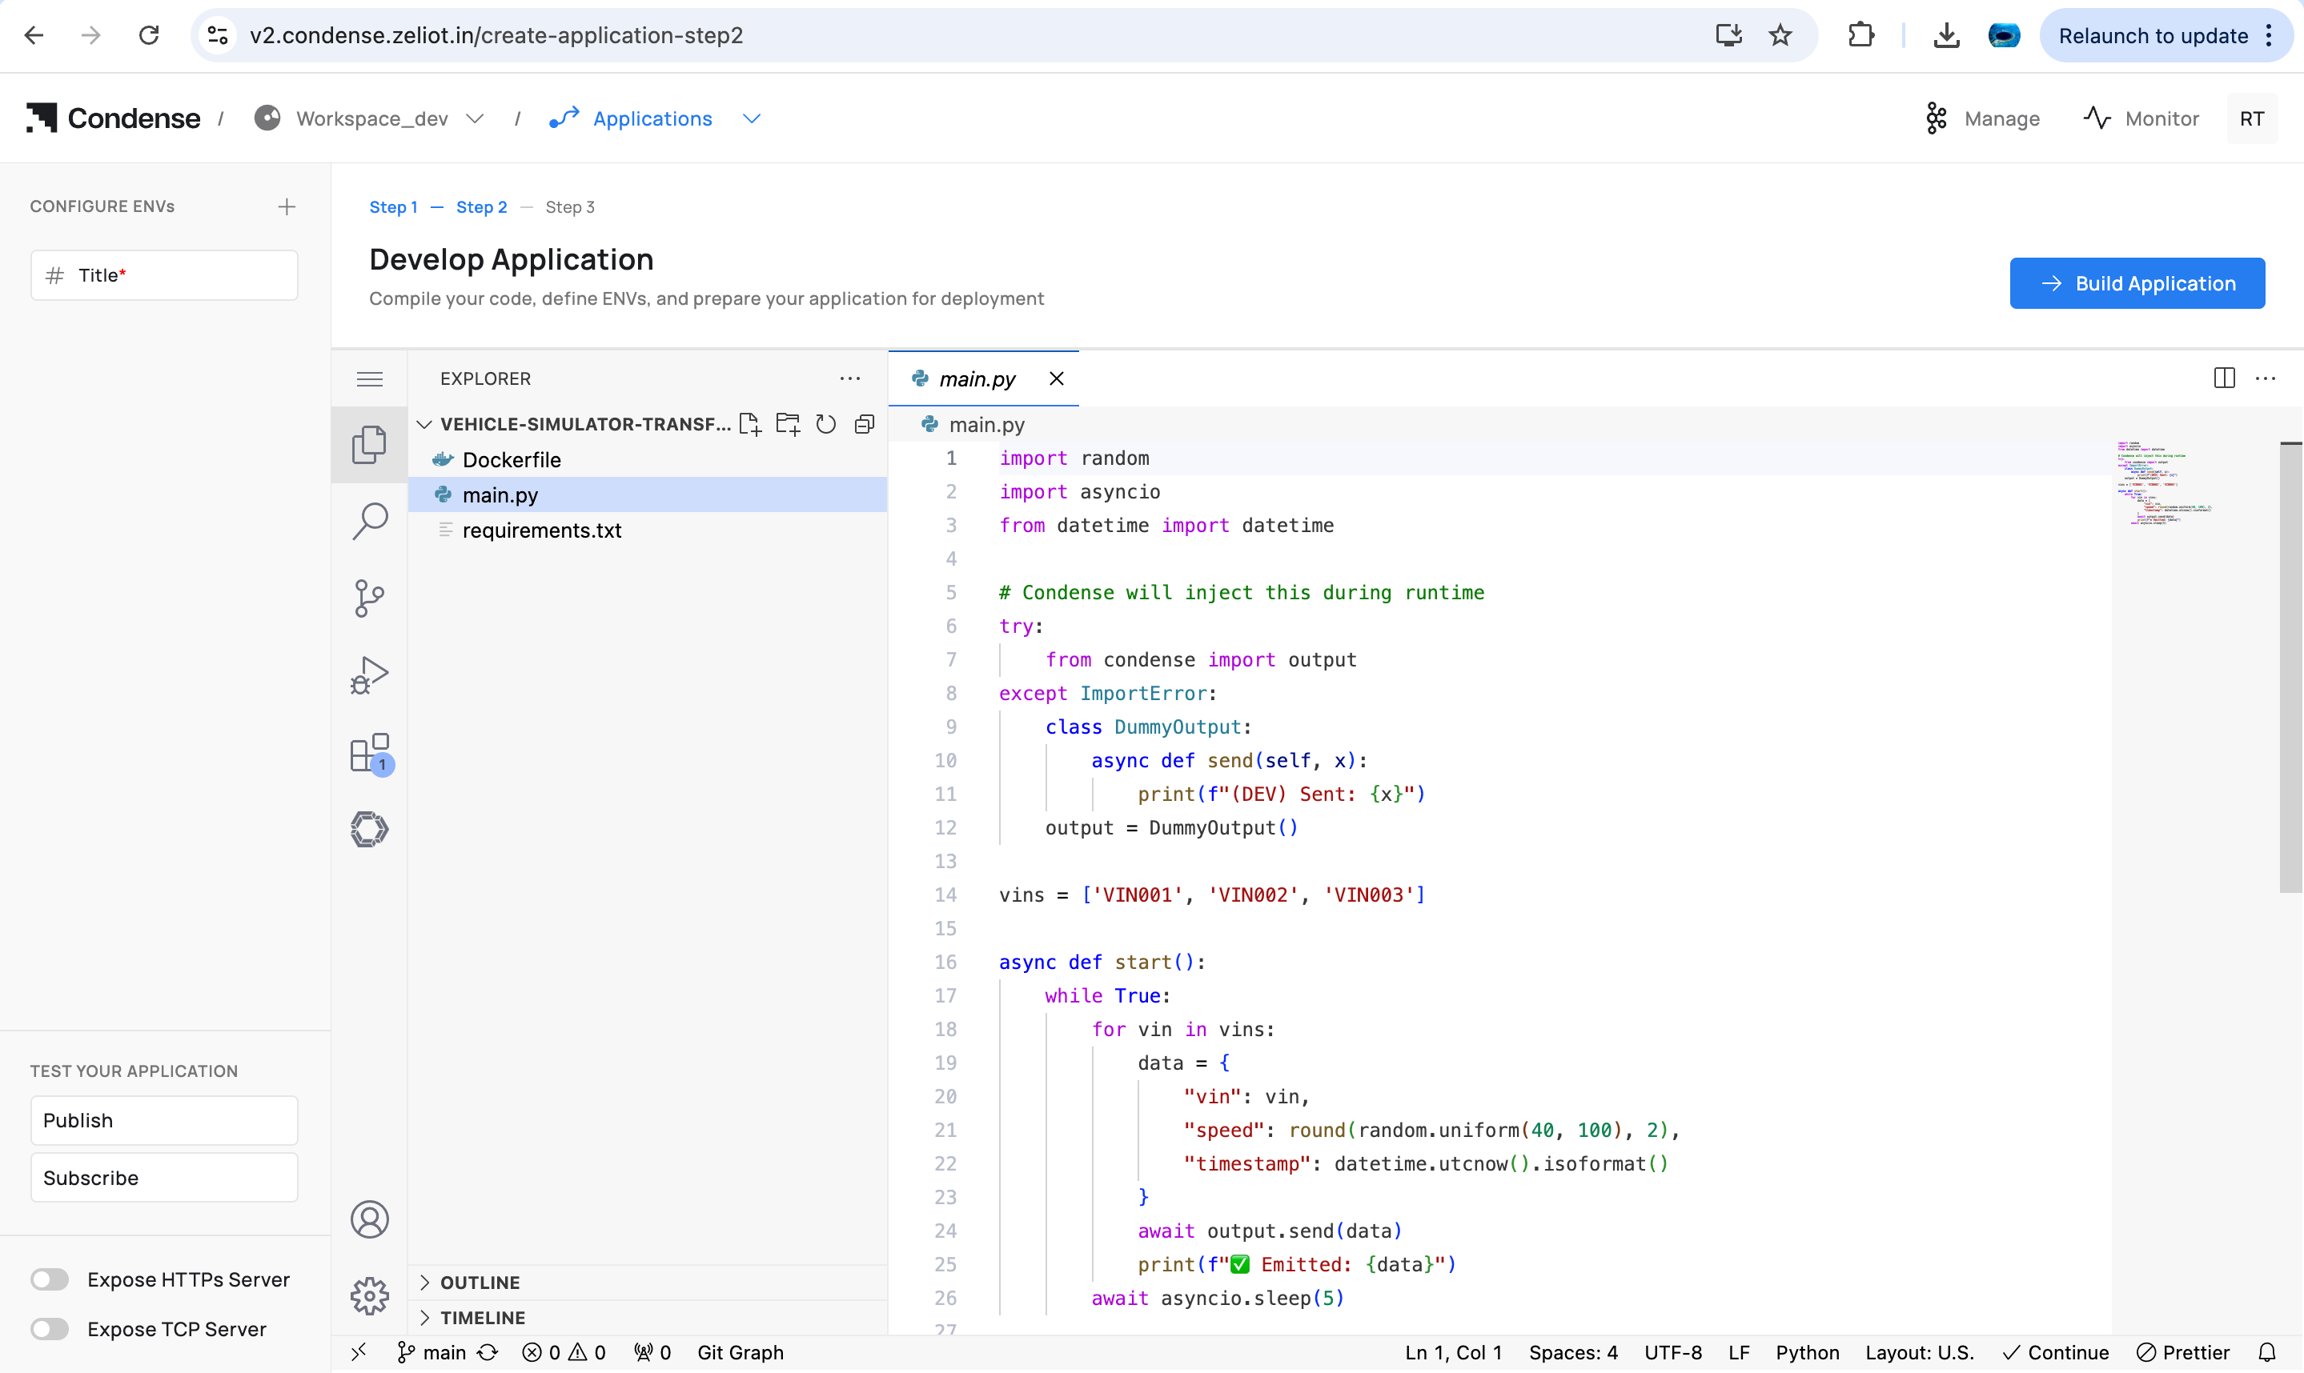
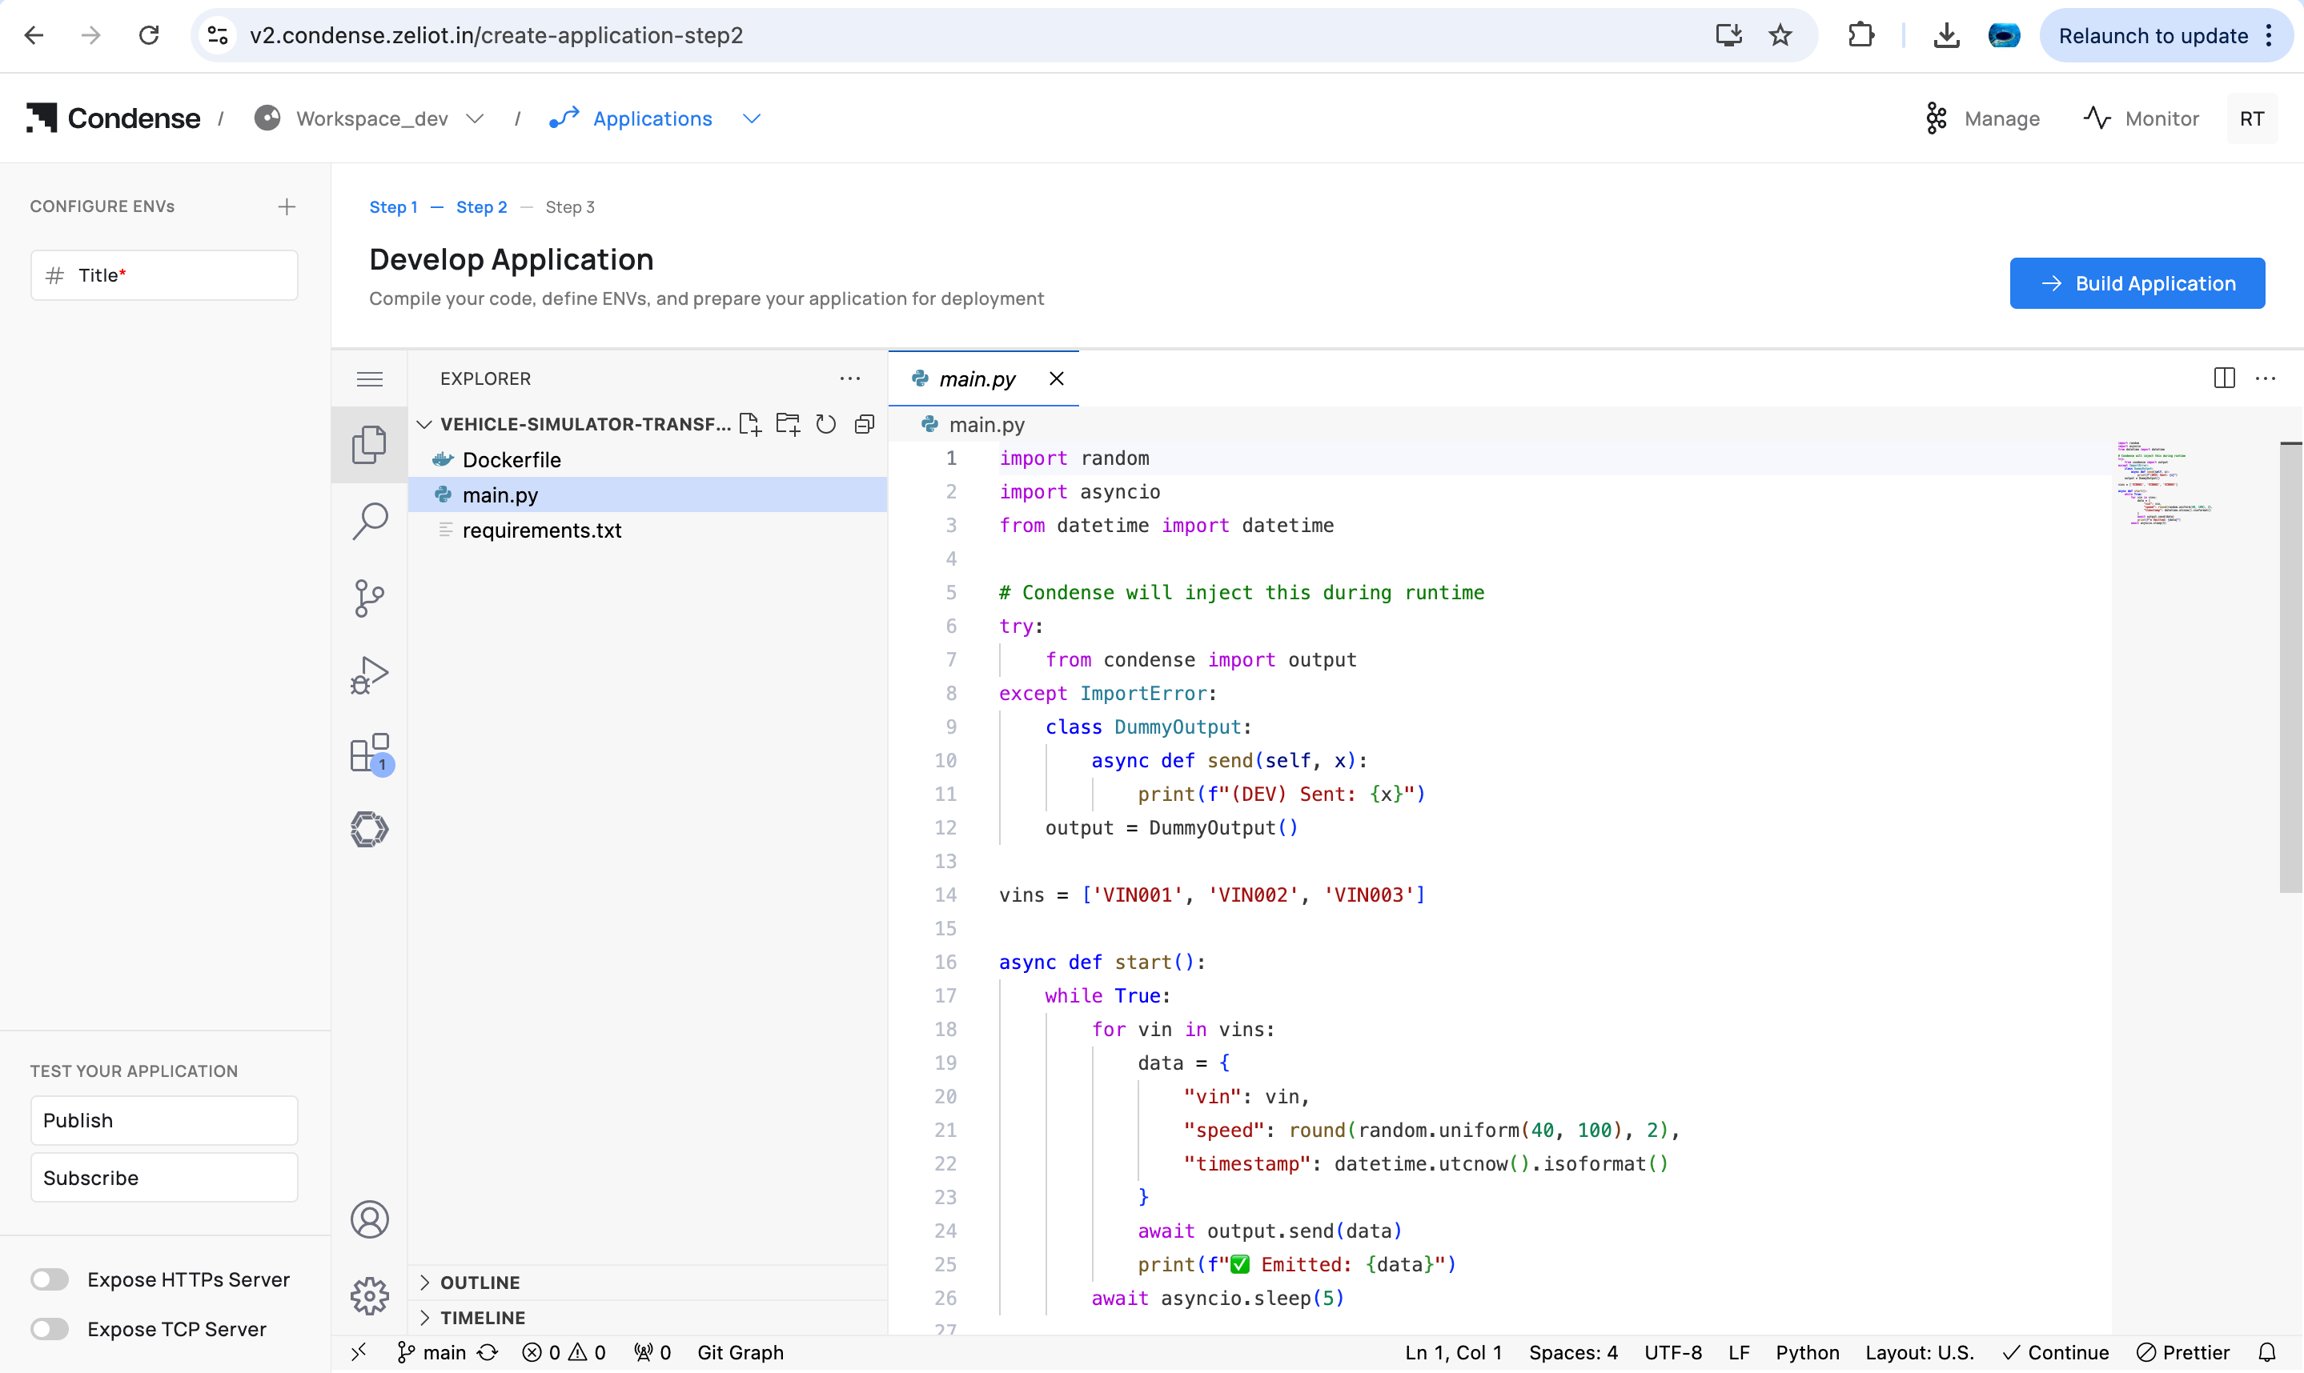
IDE screen
Step 3 - Build the Application
Who can build: Admins, Maintainers, Developers- Click Build Application.
- Enter the Docker Image Name (registry path, e.g.
registry/acme/my-transform) and Tag (e.g.v1.0.0). - Click Start Build and monitor the Build Logs in real time.
- If the build fails, review the error output, fix code/ENVs/Dockerfile, and rebuild.
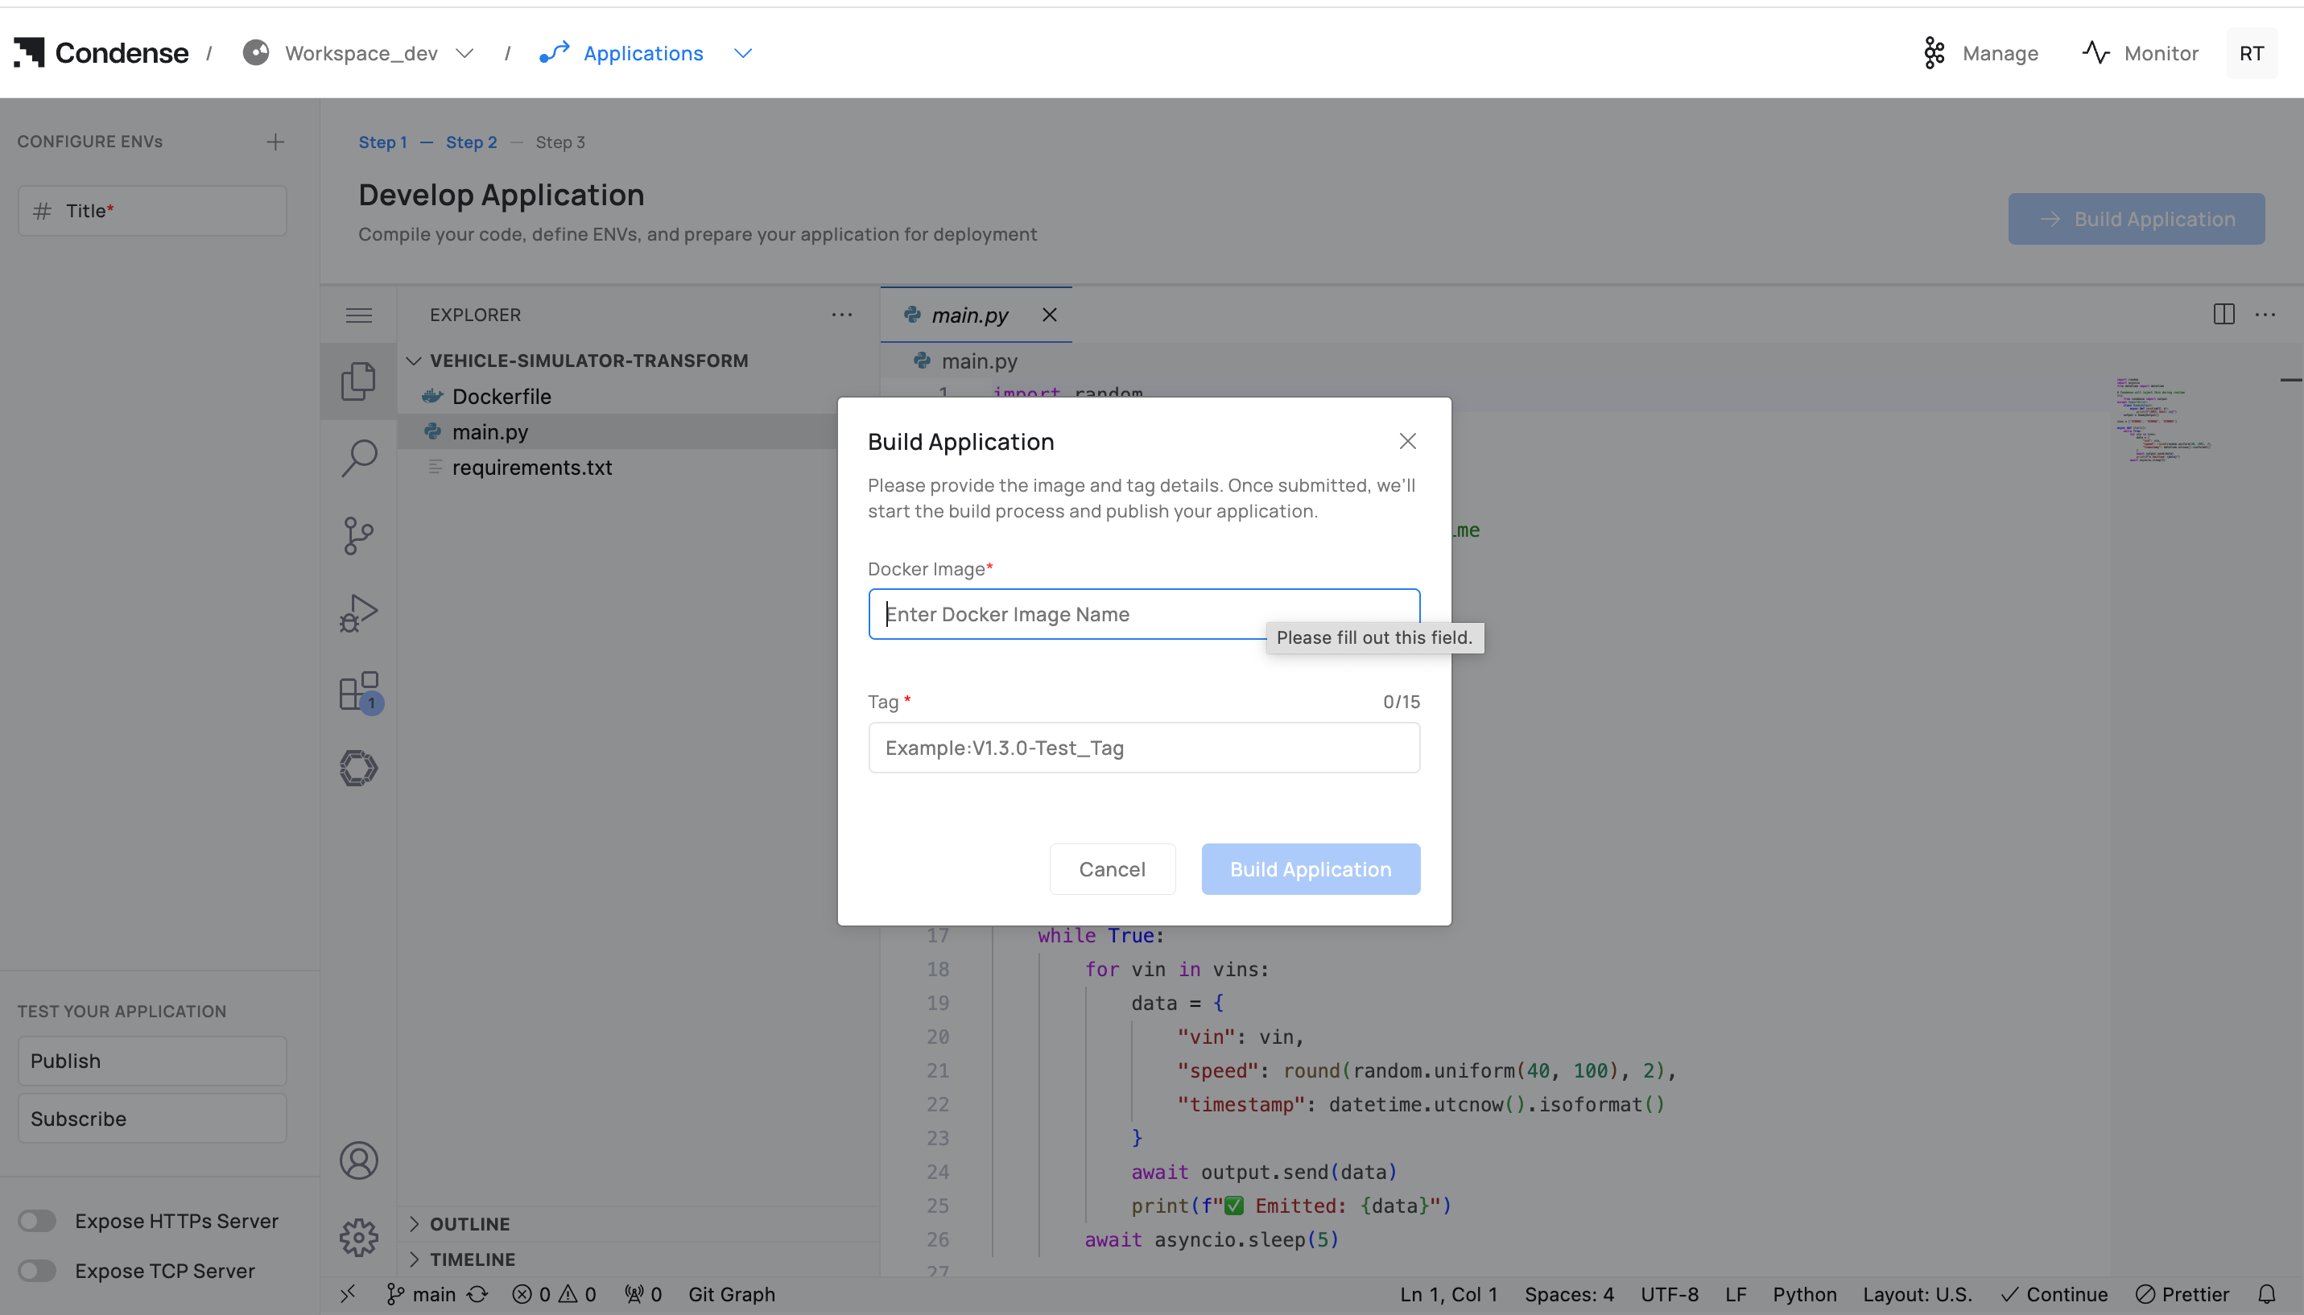
Build Application Dialog Box
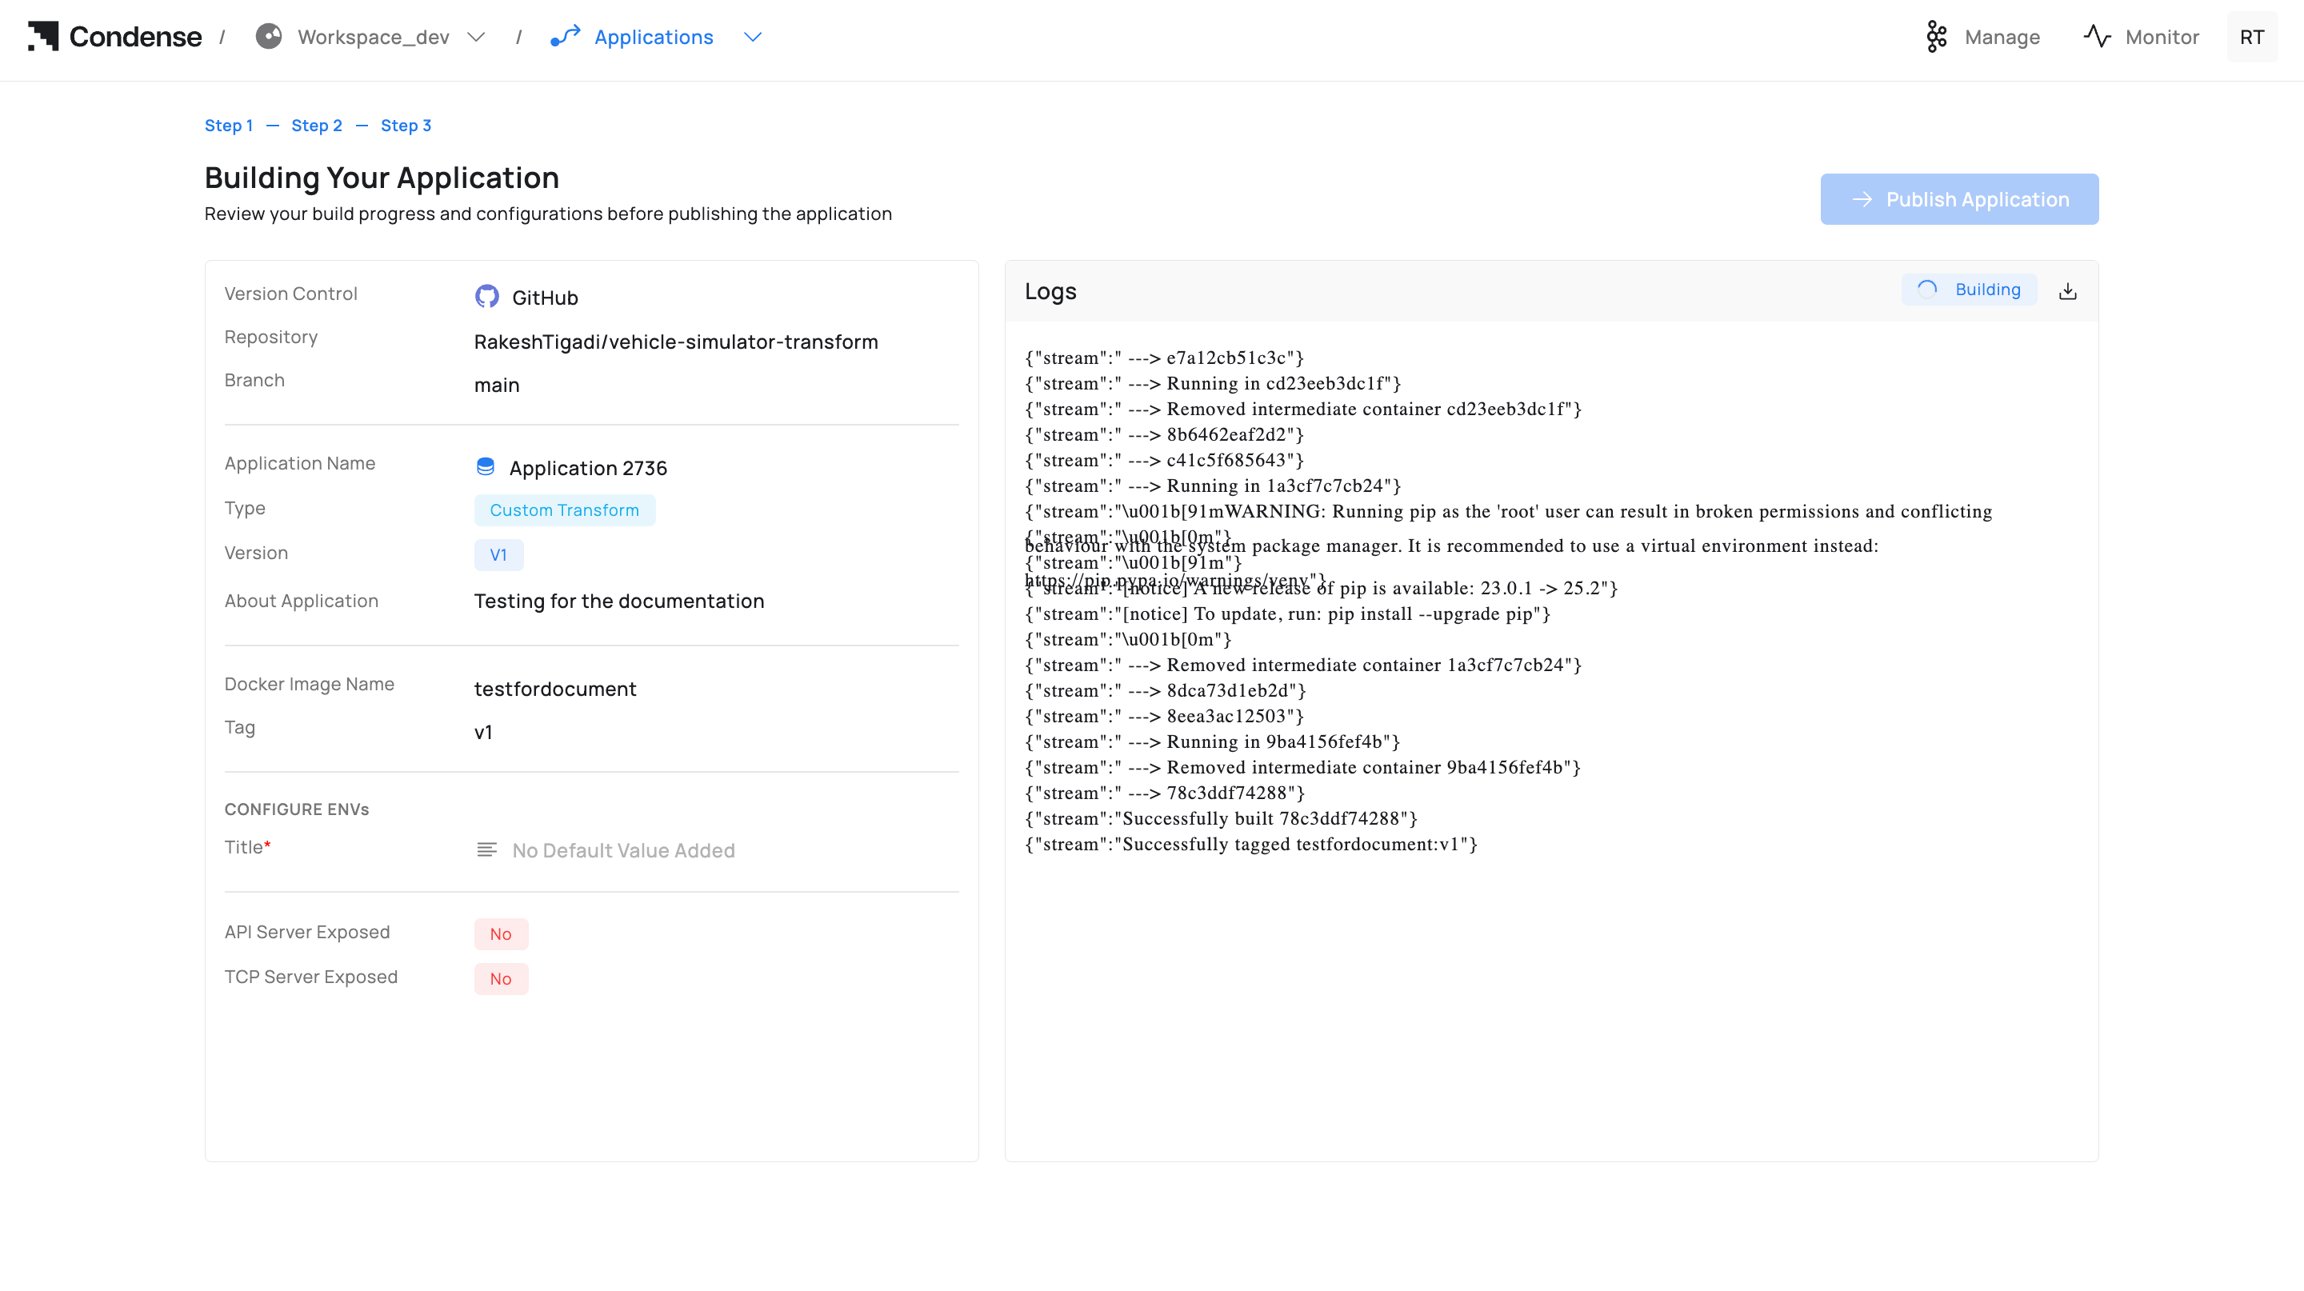
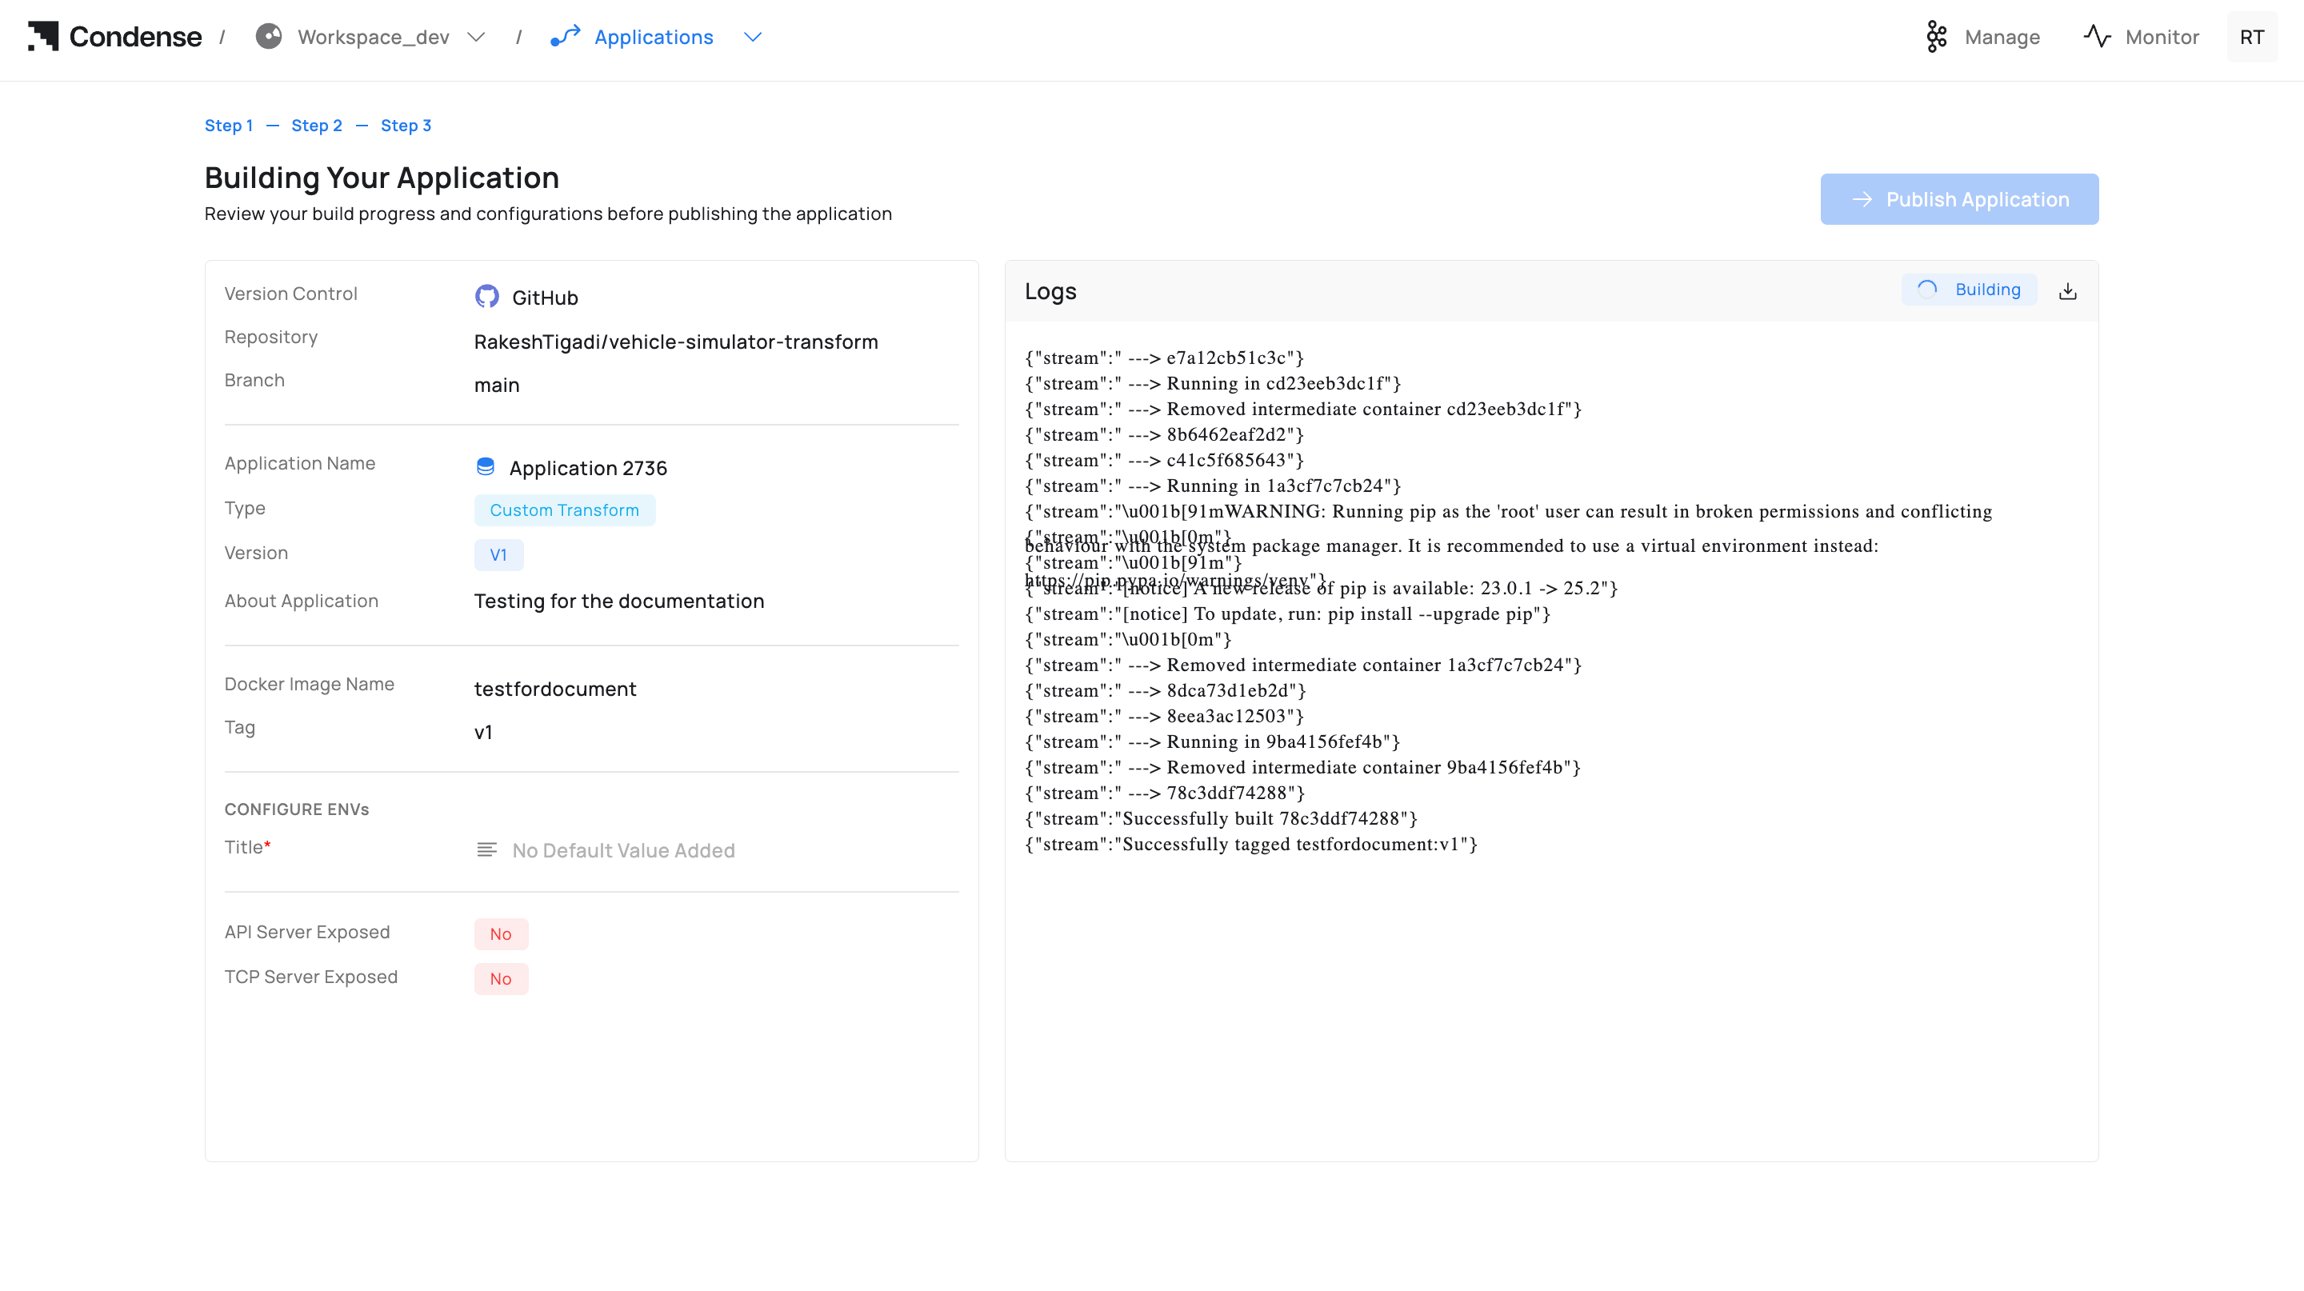
Build Logs Screen
Build tips:
- Use a fully qualified image name for external registries.
- Some registries enforce lowercase tags - prefer lowercase alphanumerics, dots, and dashes.
- Pass secrets via ENVs; do not bake them into the image.
Step 4 - Publish the Application
Who can publish: Admins, Maintainers
- Click Publish Application.
- Confirm Publish as a custom: select Transform.
- Confirm the Version and add optional release notes.
- Click Publish.
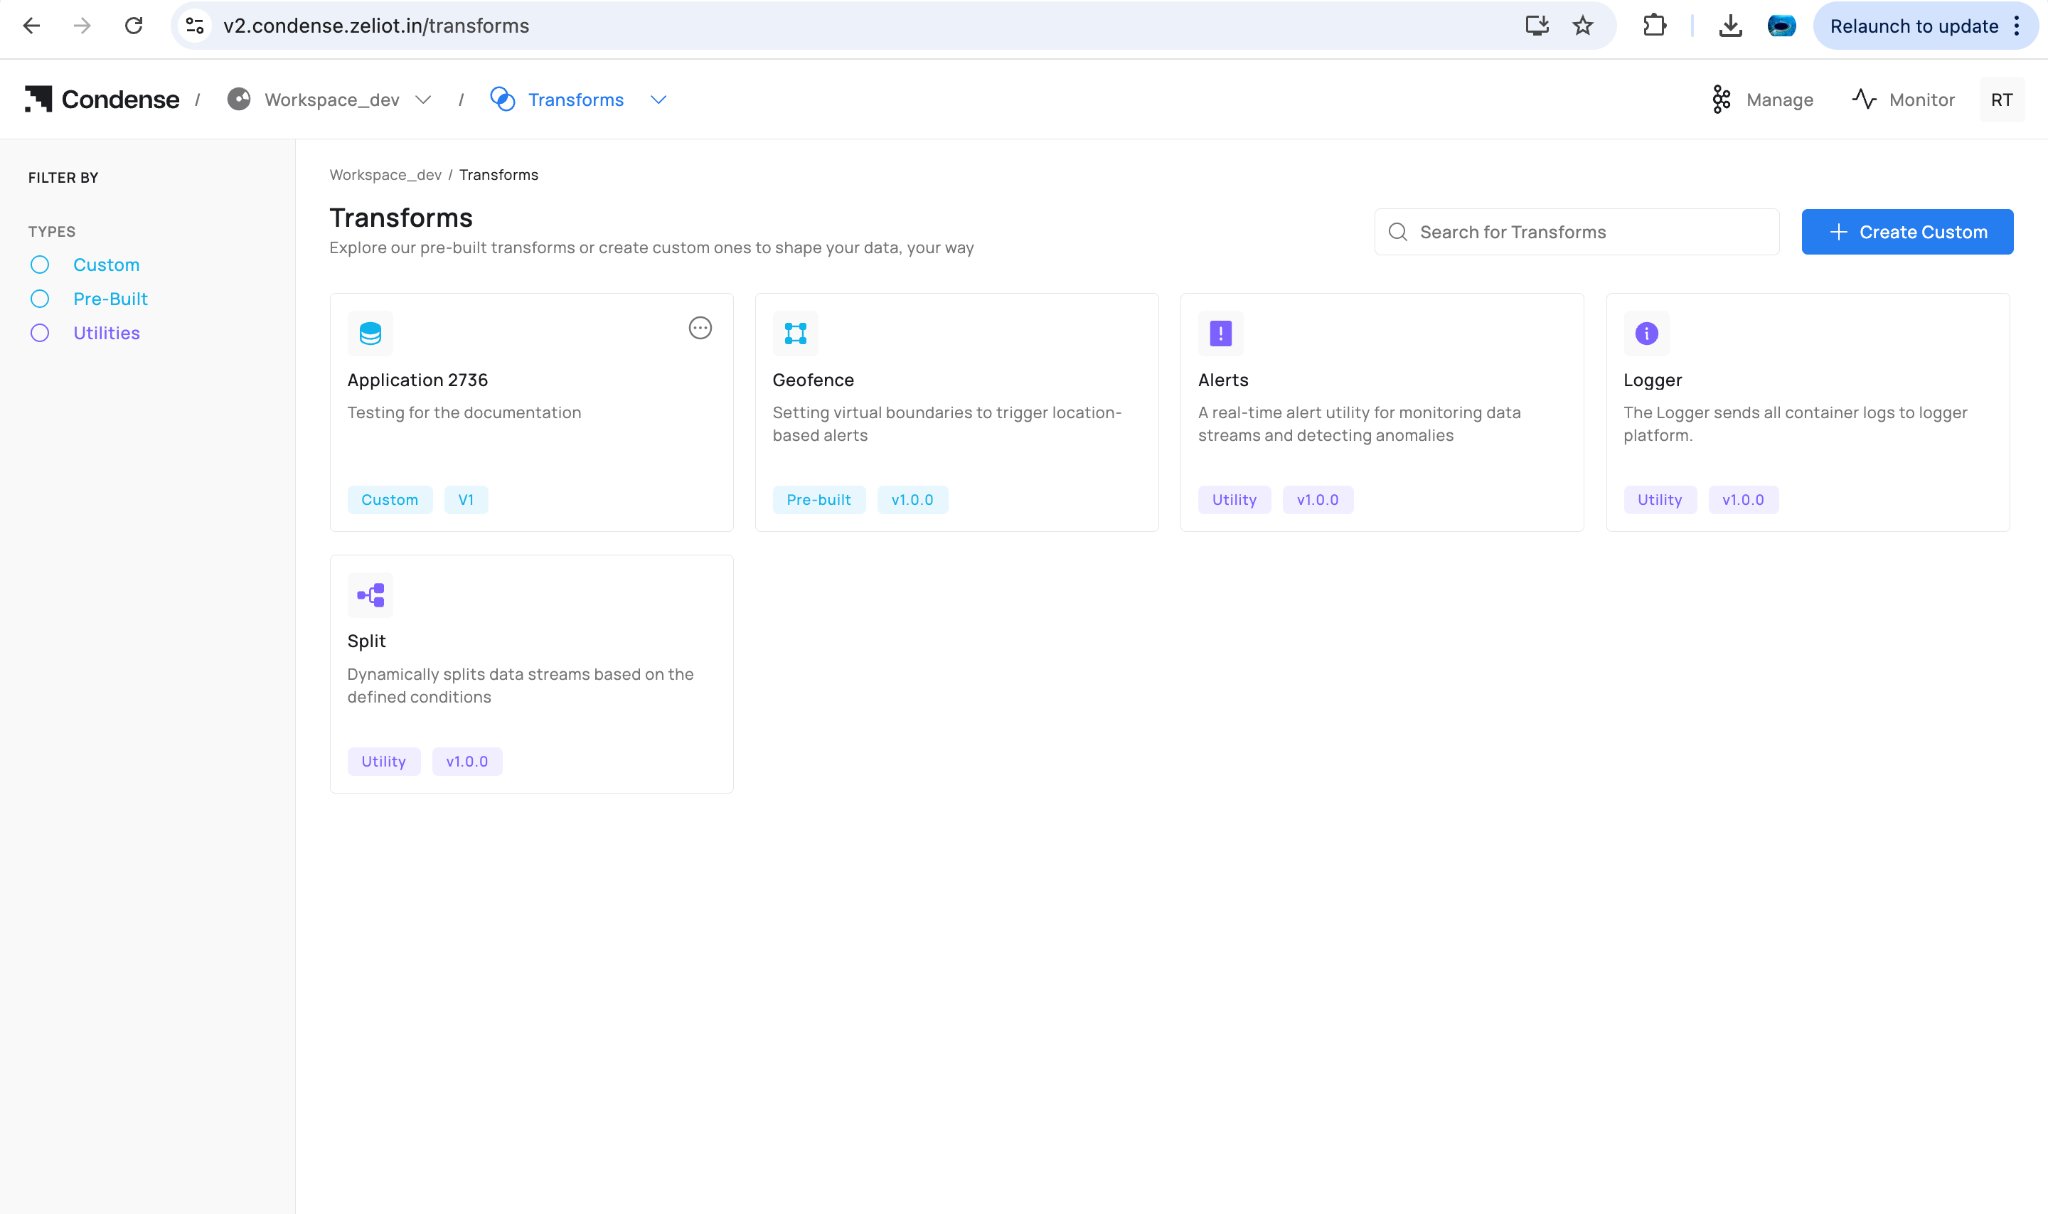
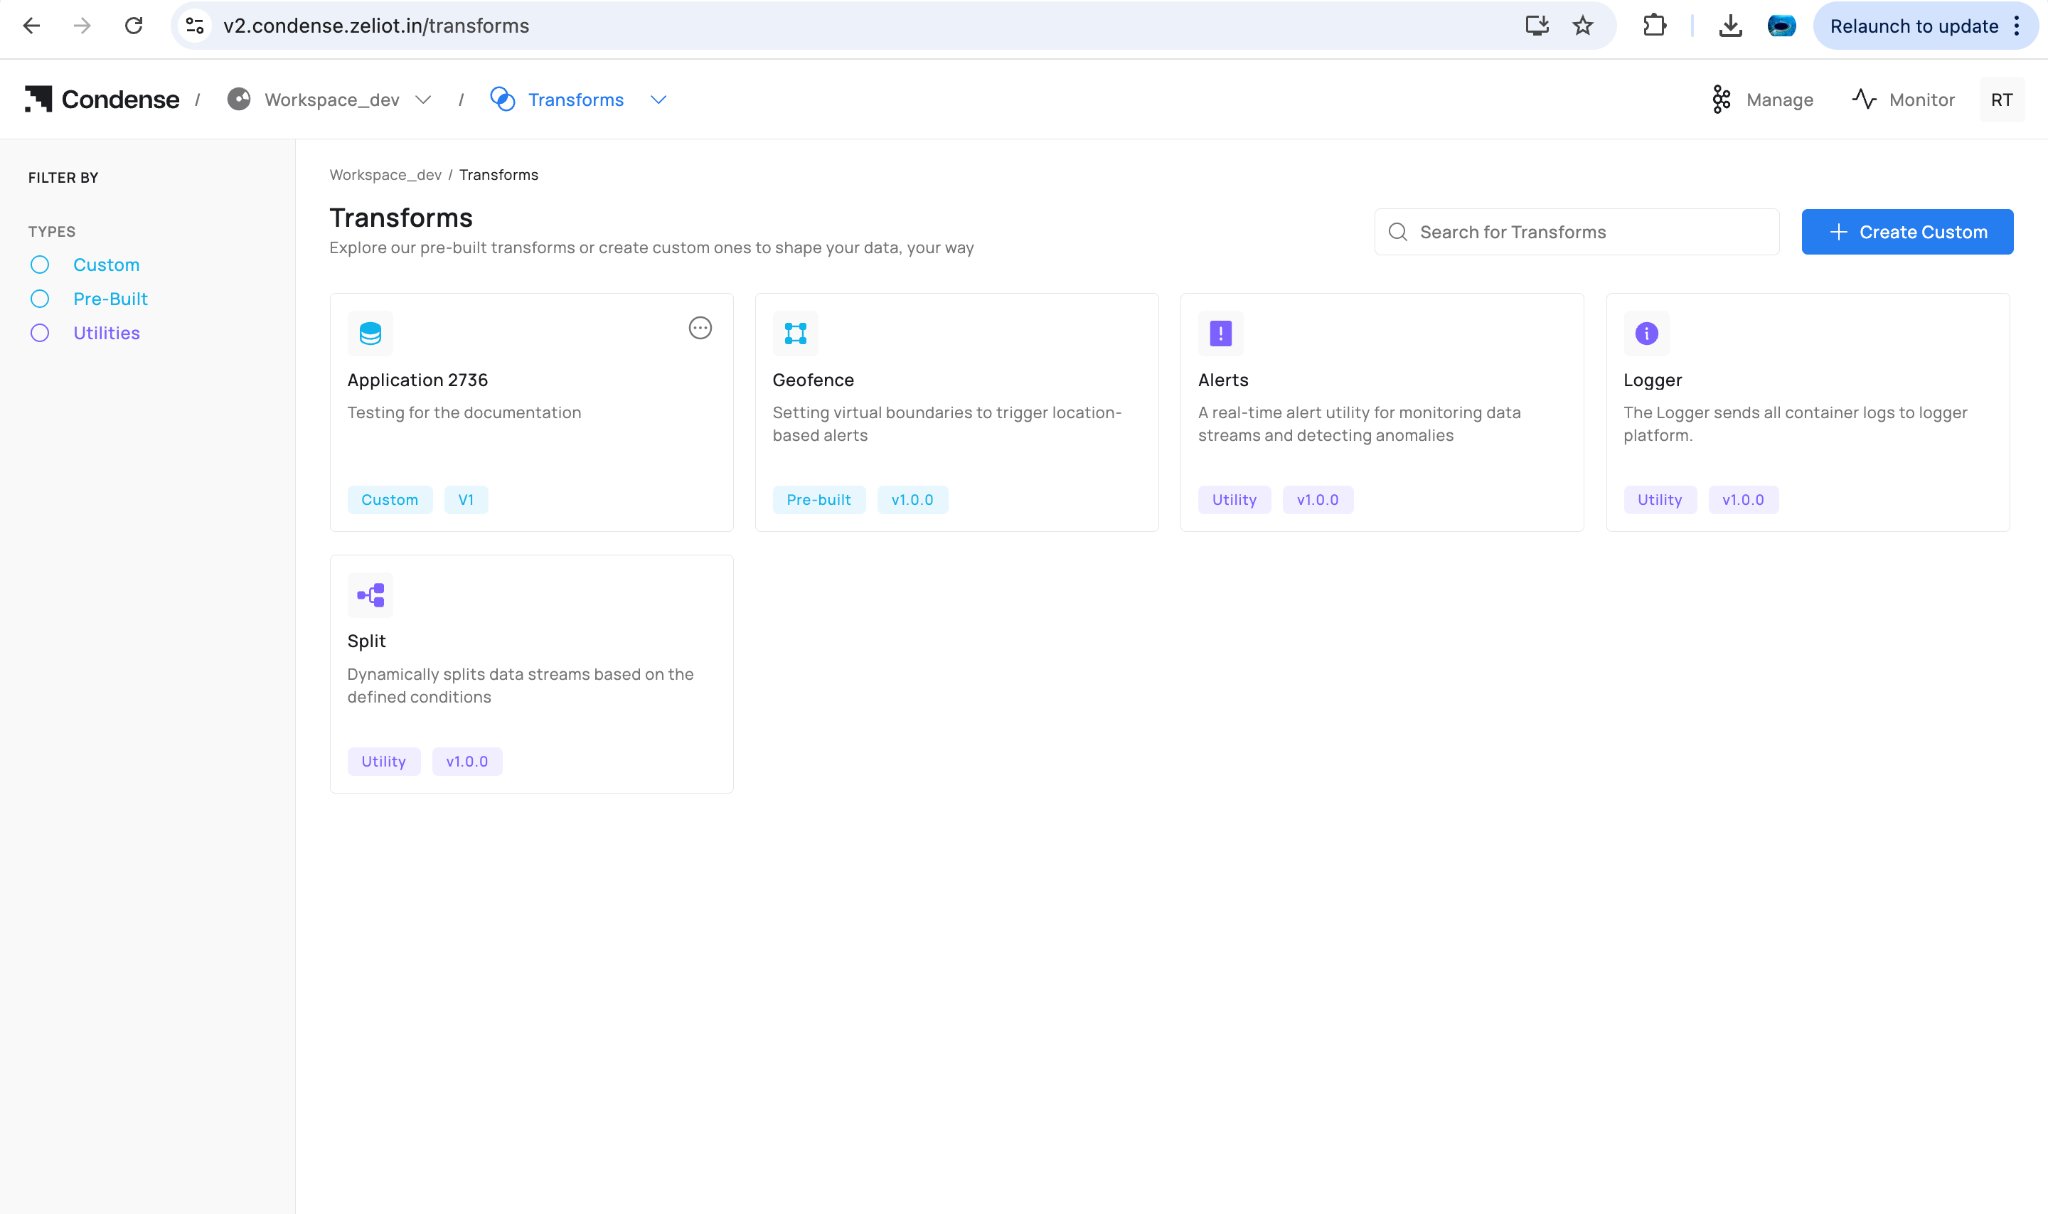
Publish Application Screen
Step 5 - Deploy to the Pipeline
Who can deploy: Workspace Admins, Maintainers
- Go to the workspace pipeline editor.
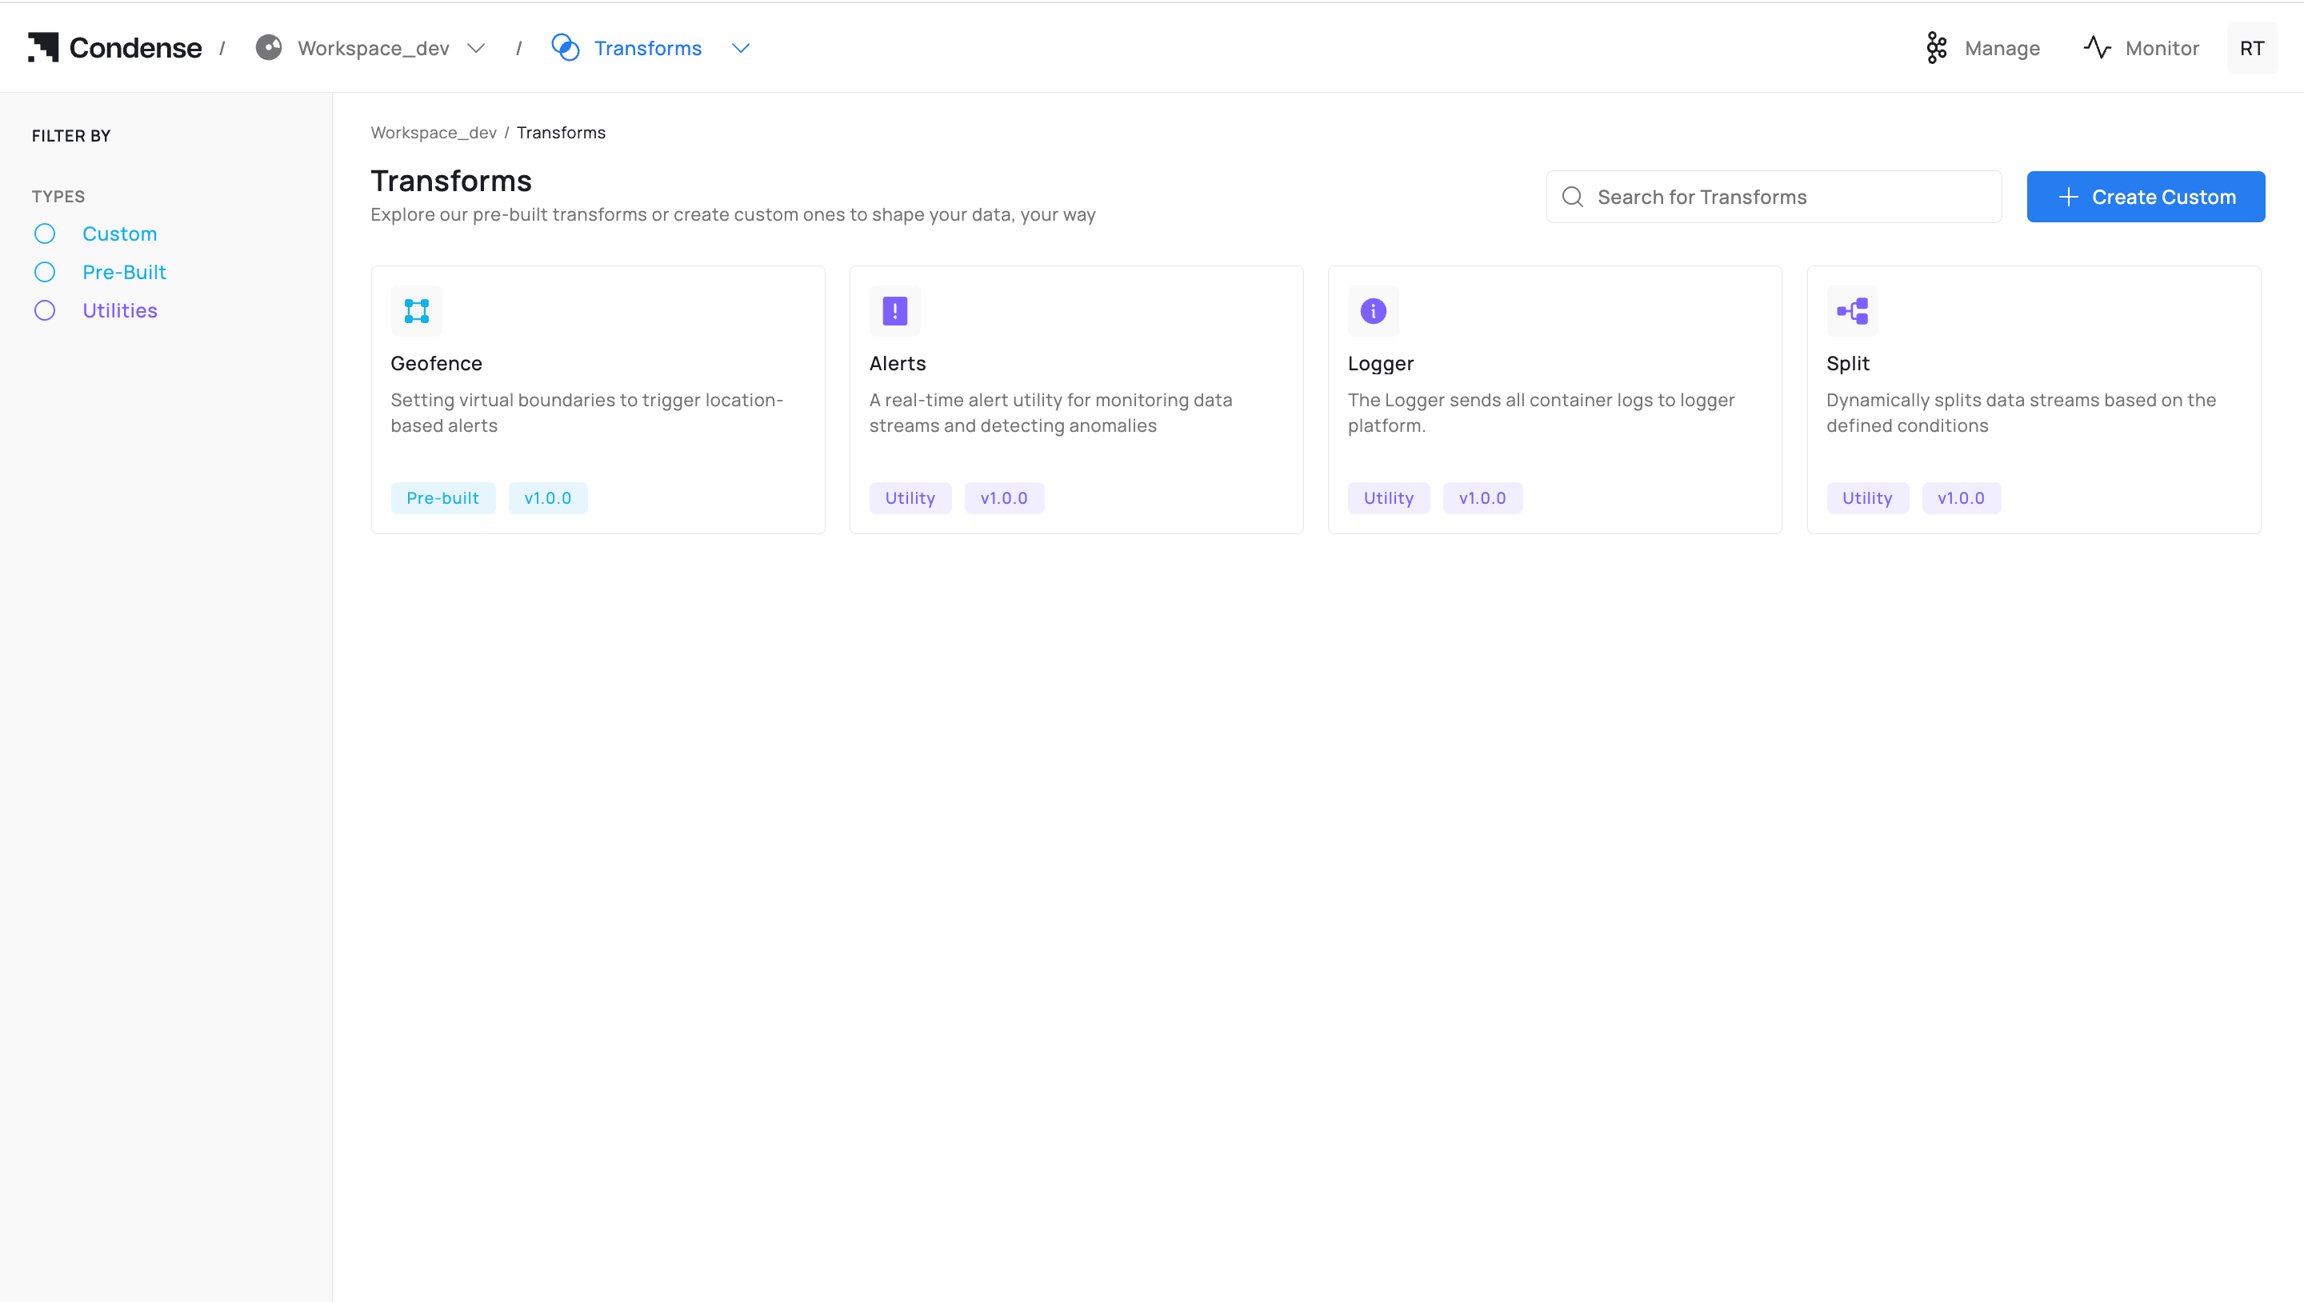
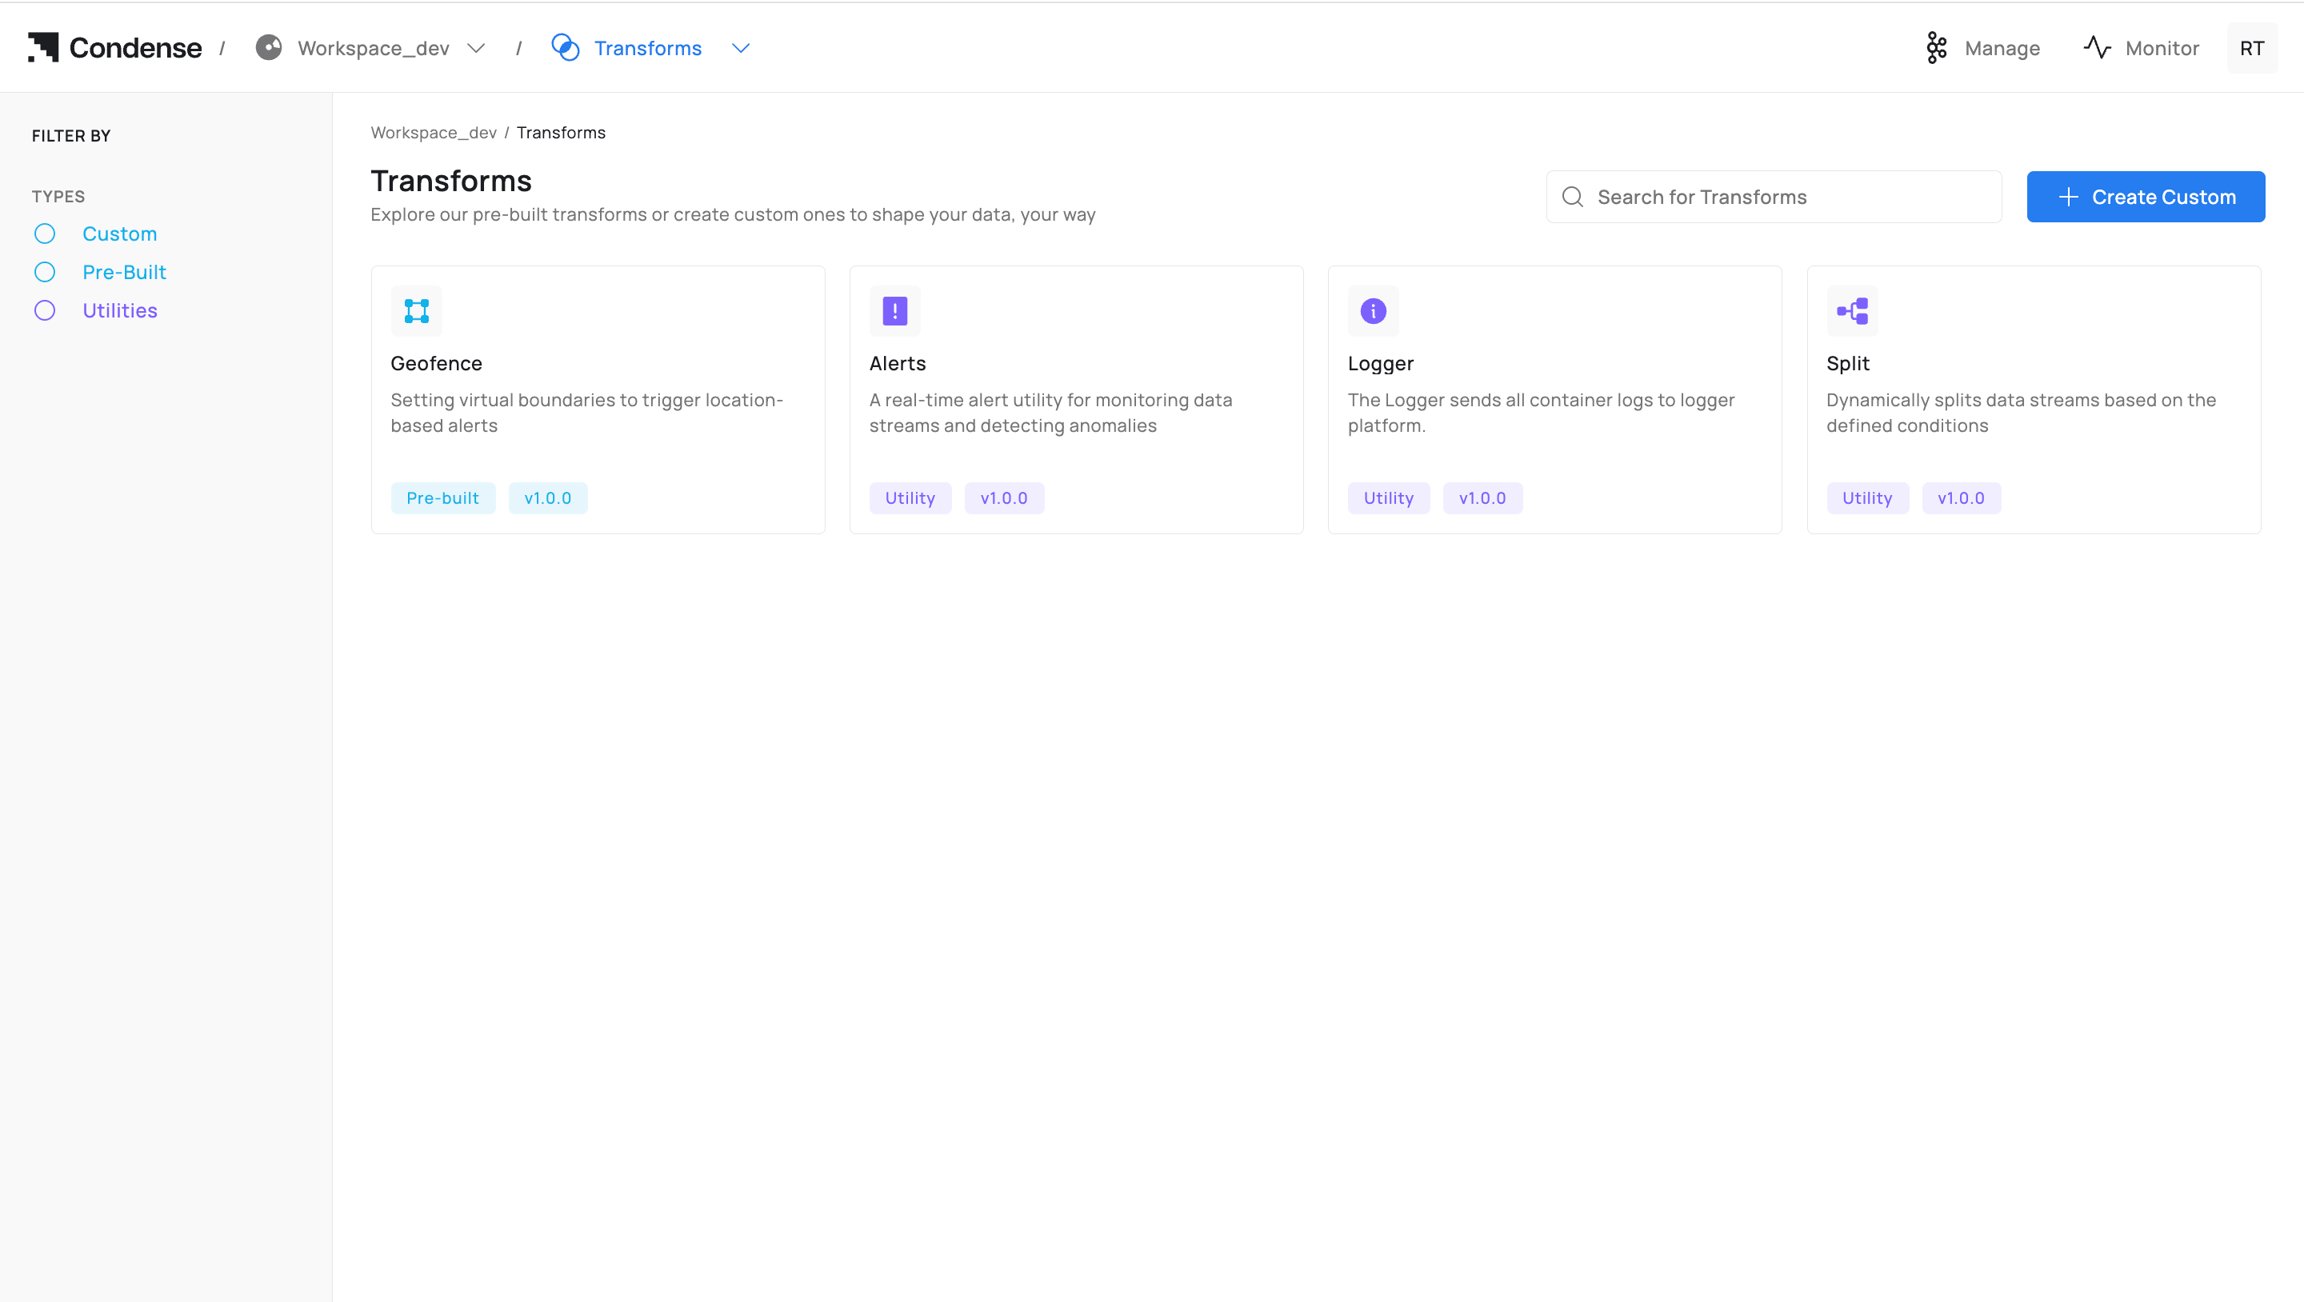
Pipeline Editor
- Click Add Transform.
- Select Custom category → choose your published application and version.
- Configure ENVs and parameters.
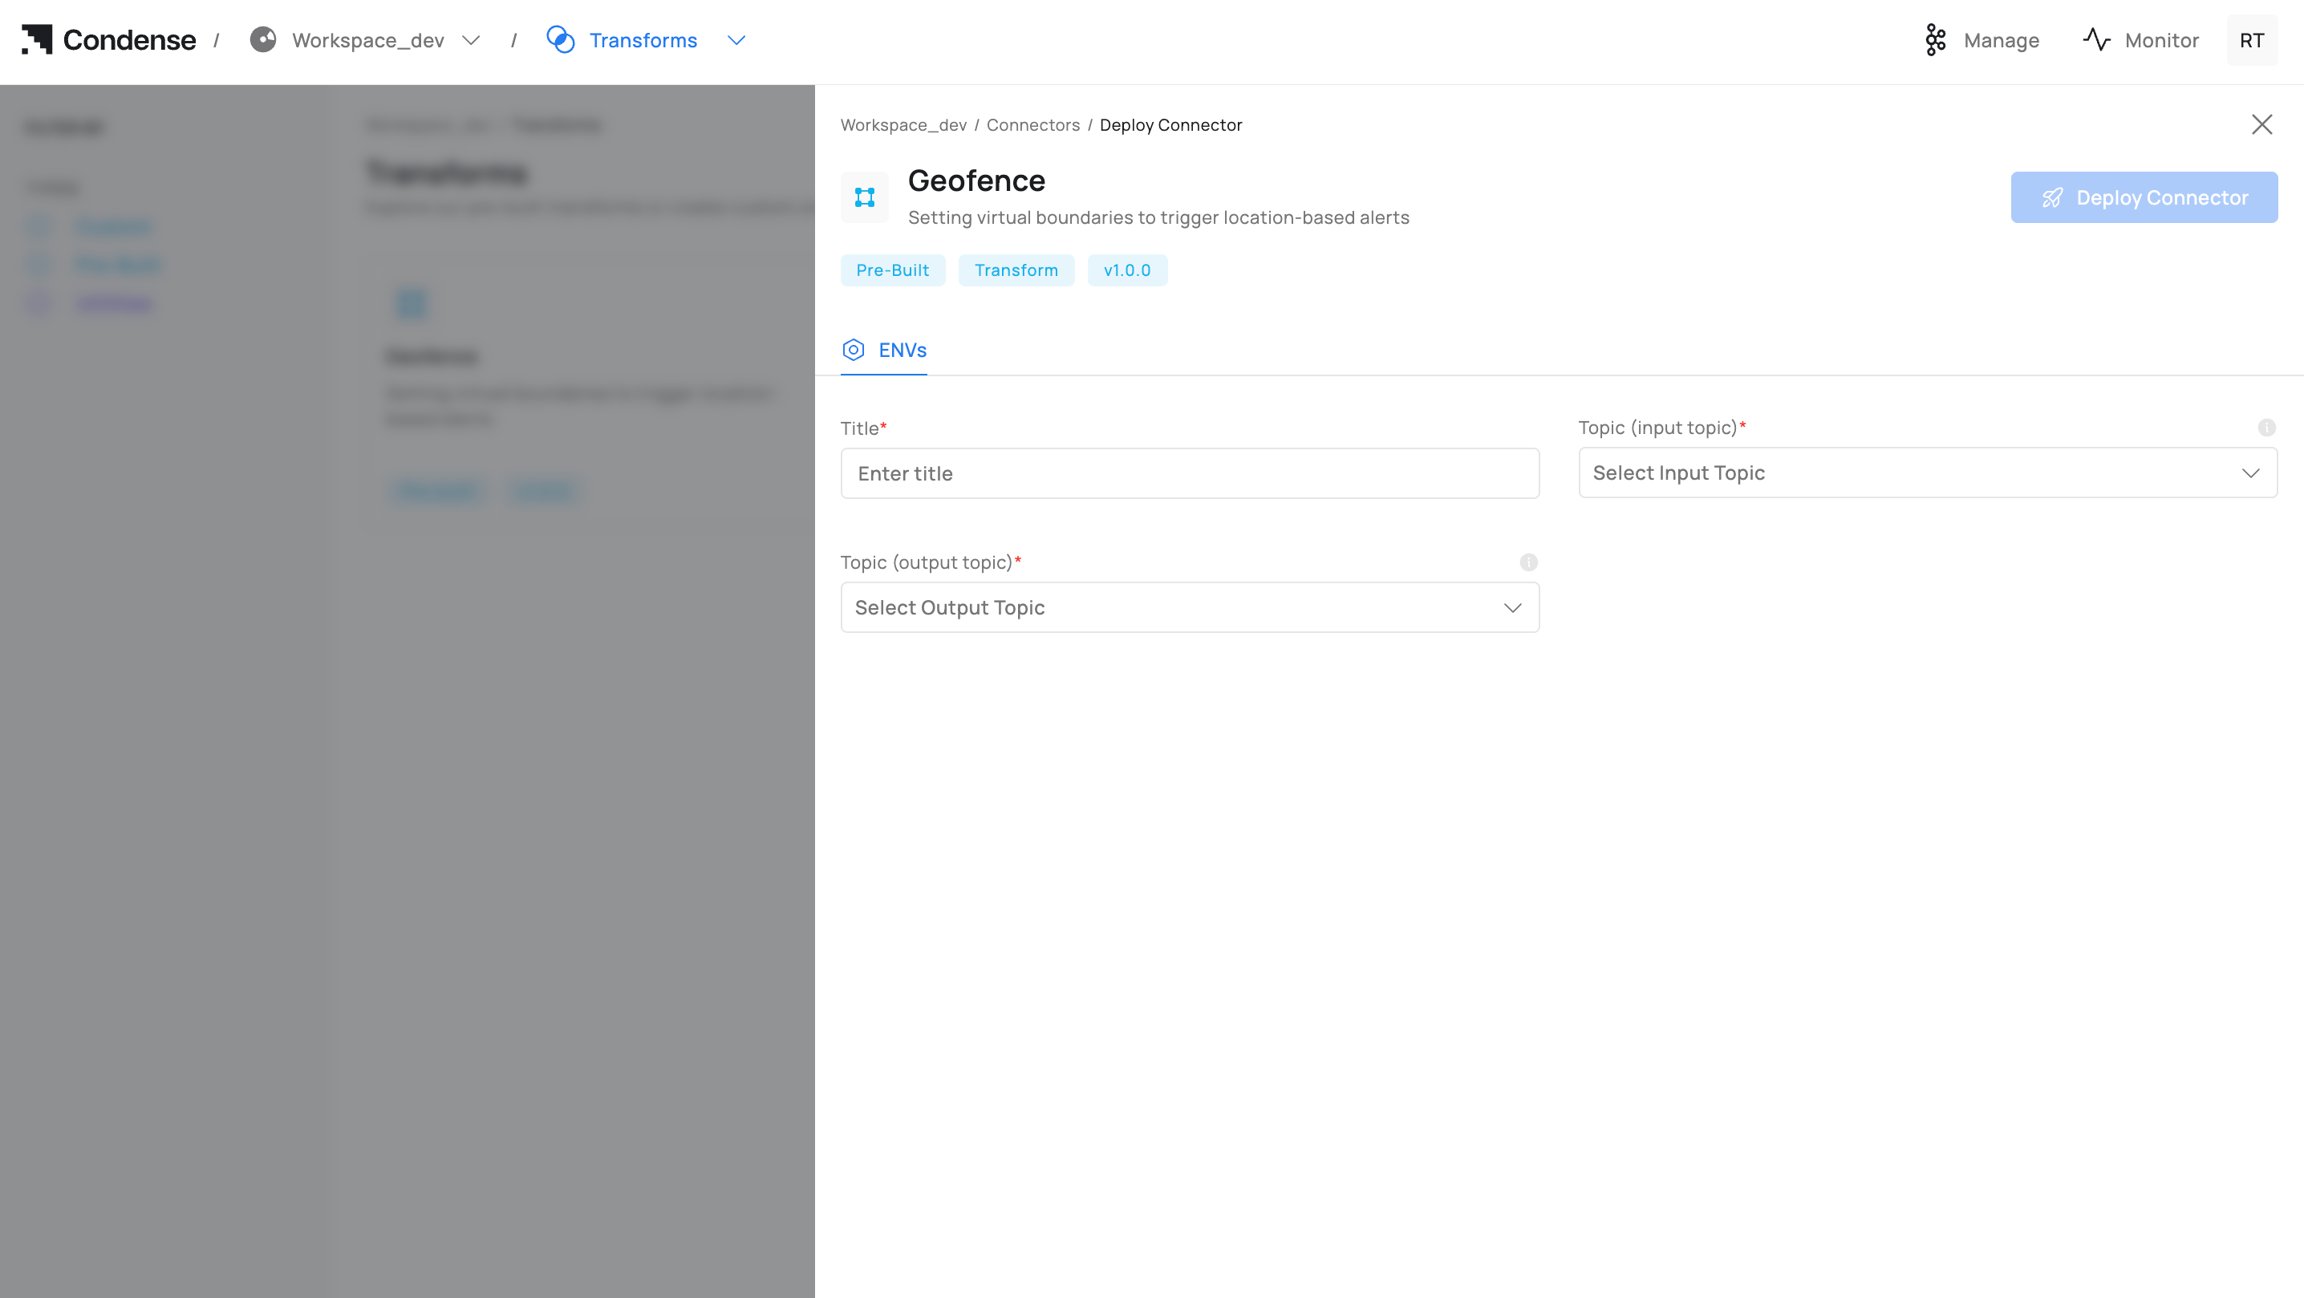
Configure Transform
- Click Save and Deploy.
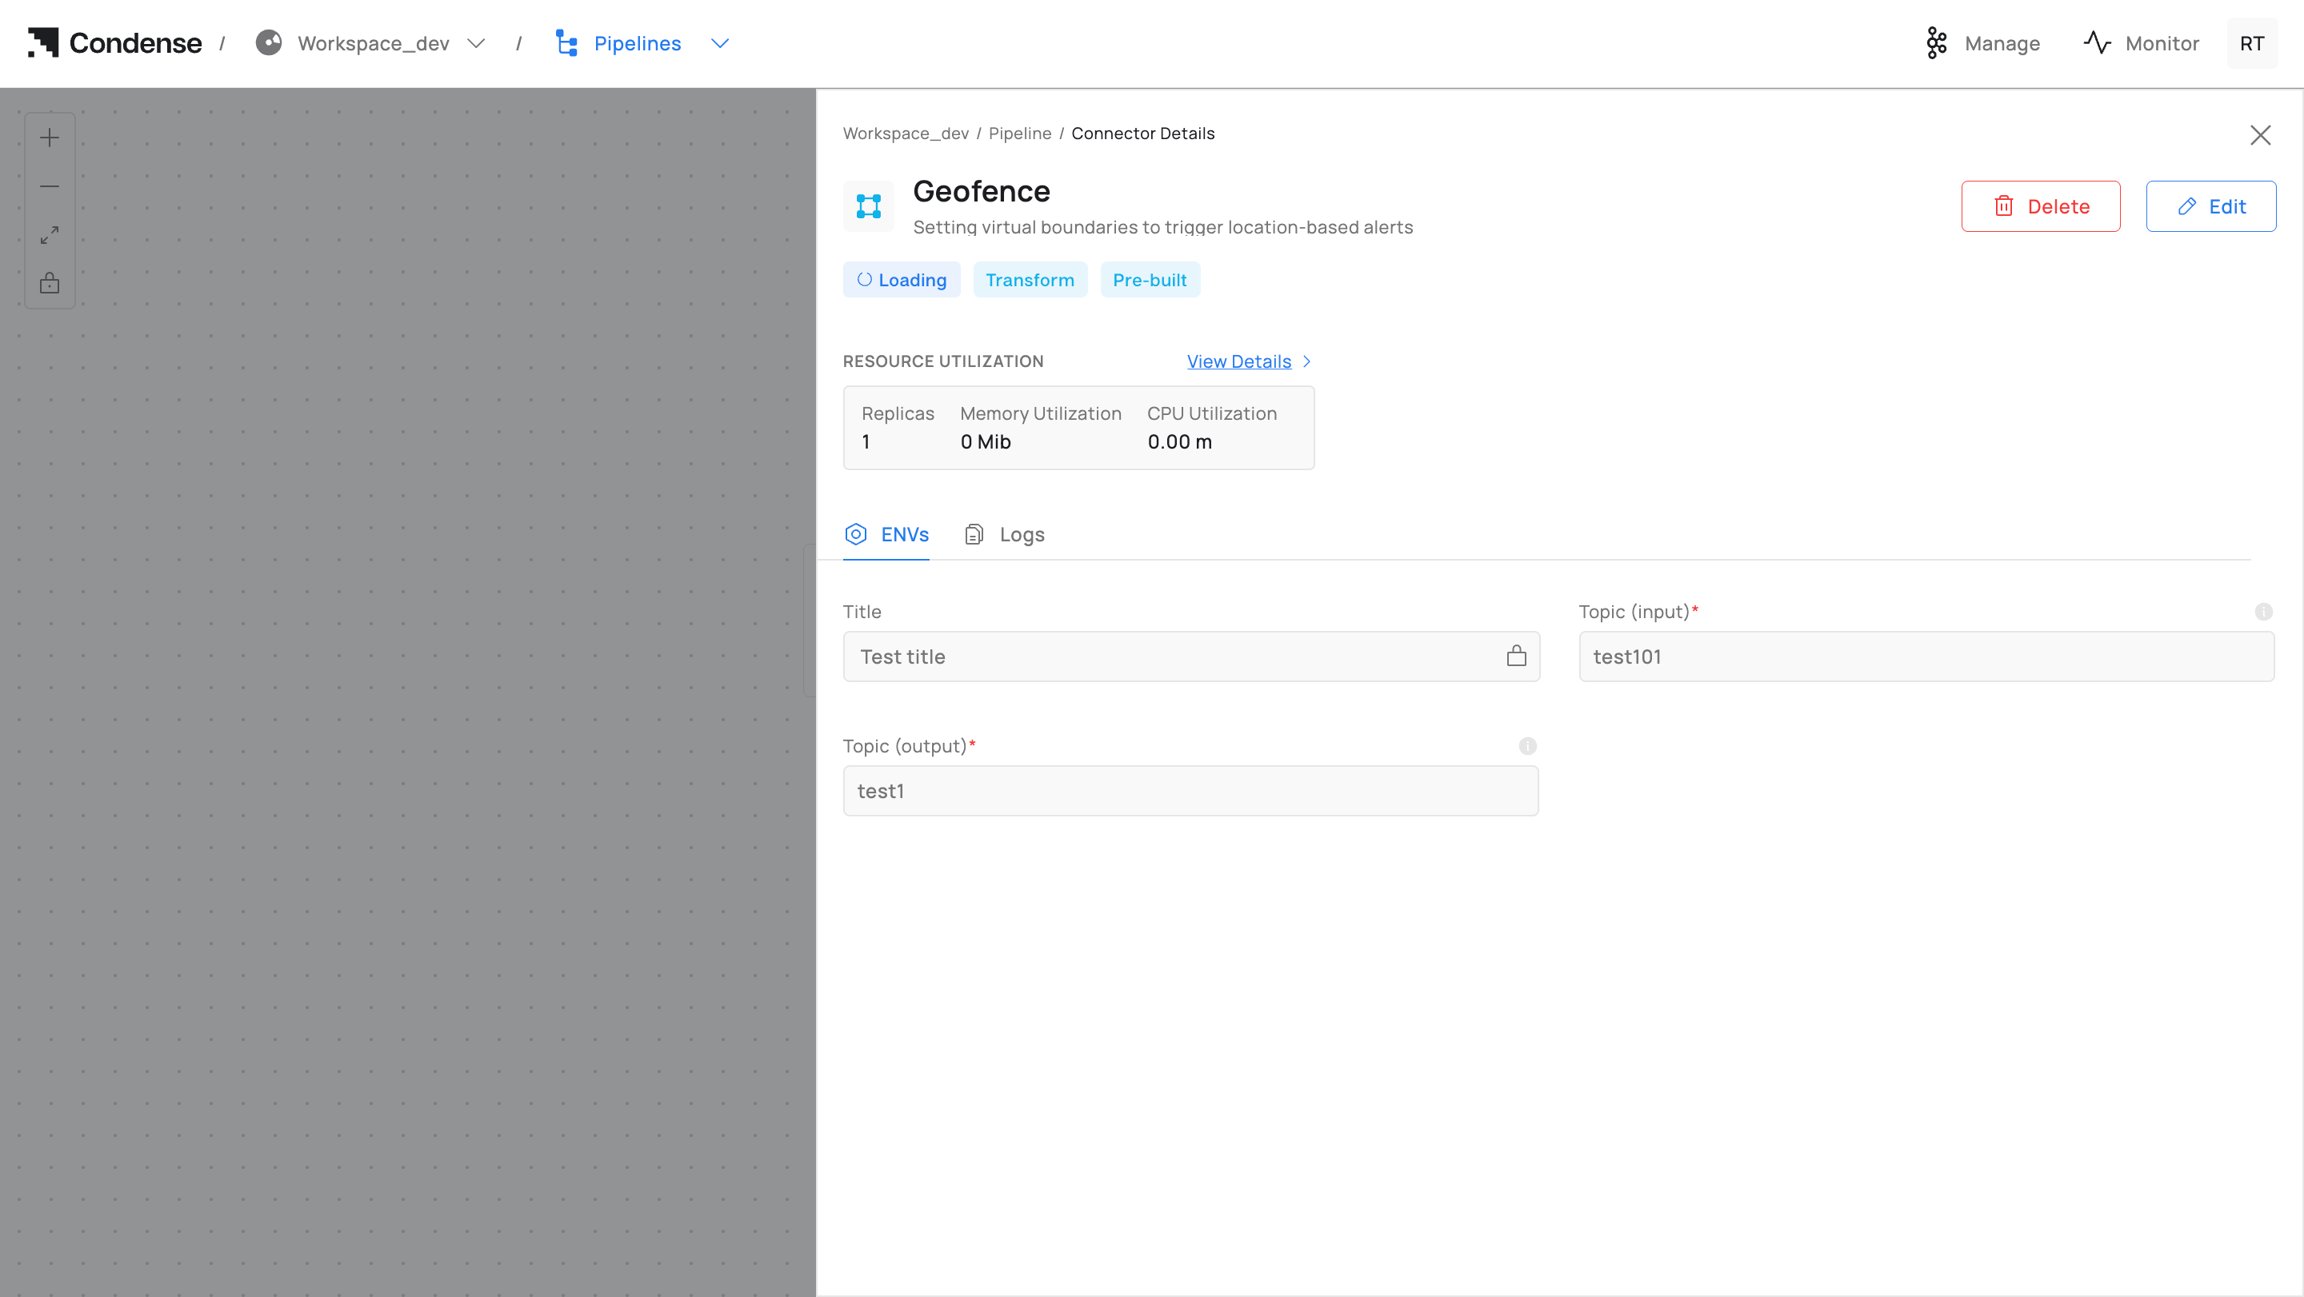
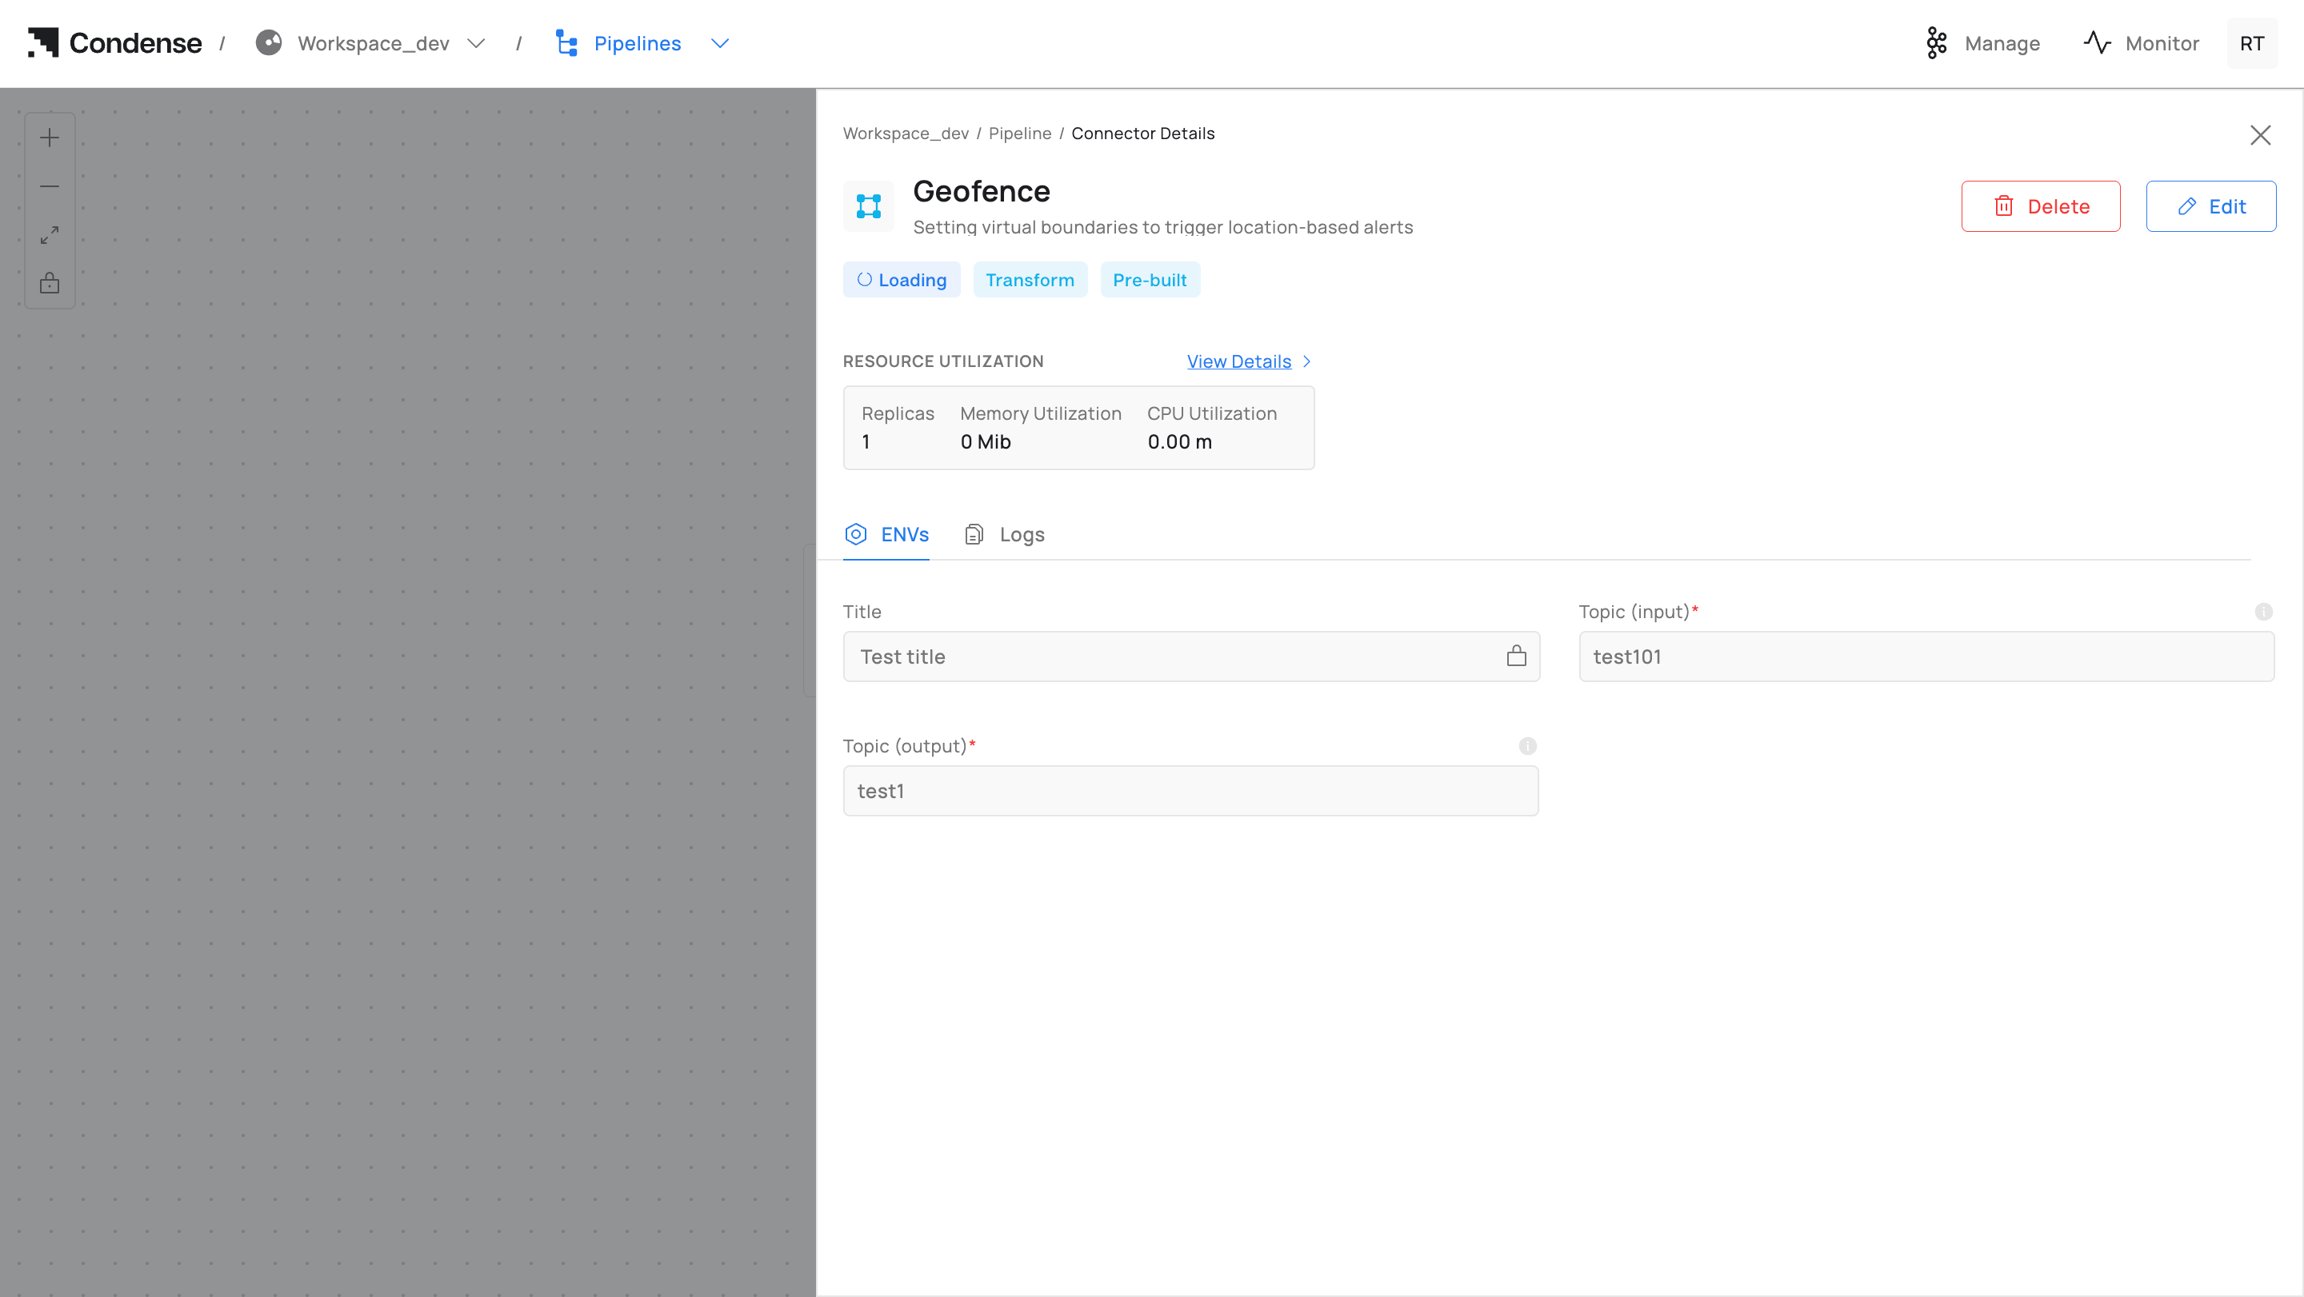
Deployed Transform
Step 6 - Update or Roll Back a Version
To update the logic of a deployed custom transform:- Go to Applications in the workspace.
- Edit the application code in the IDE.
- Rebuild and publish a new version.
- In the pipeline editor, select the deployed transform block → click Edit → switch the Version to the new release.
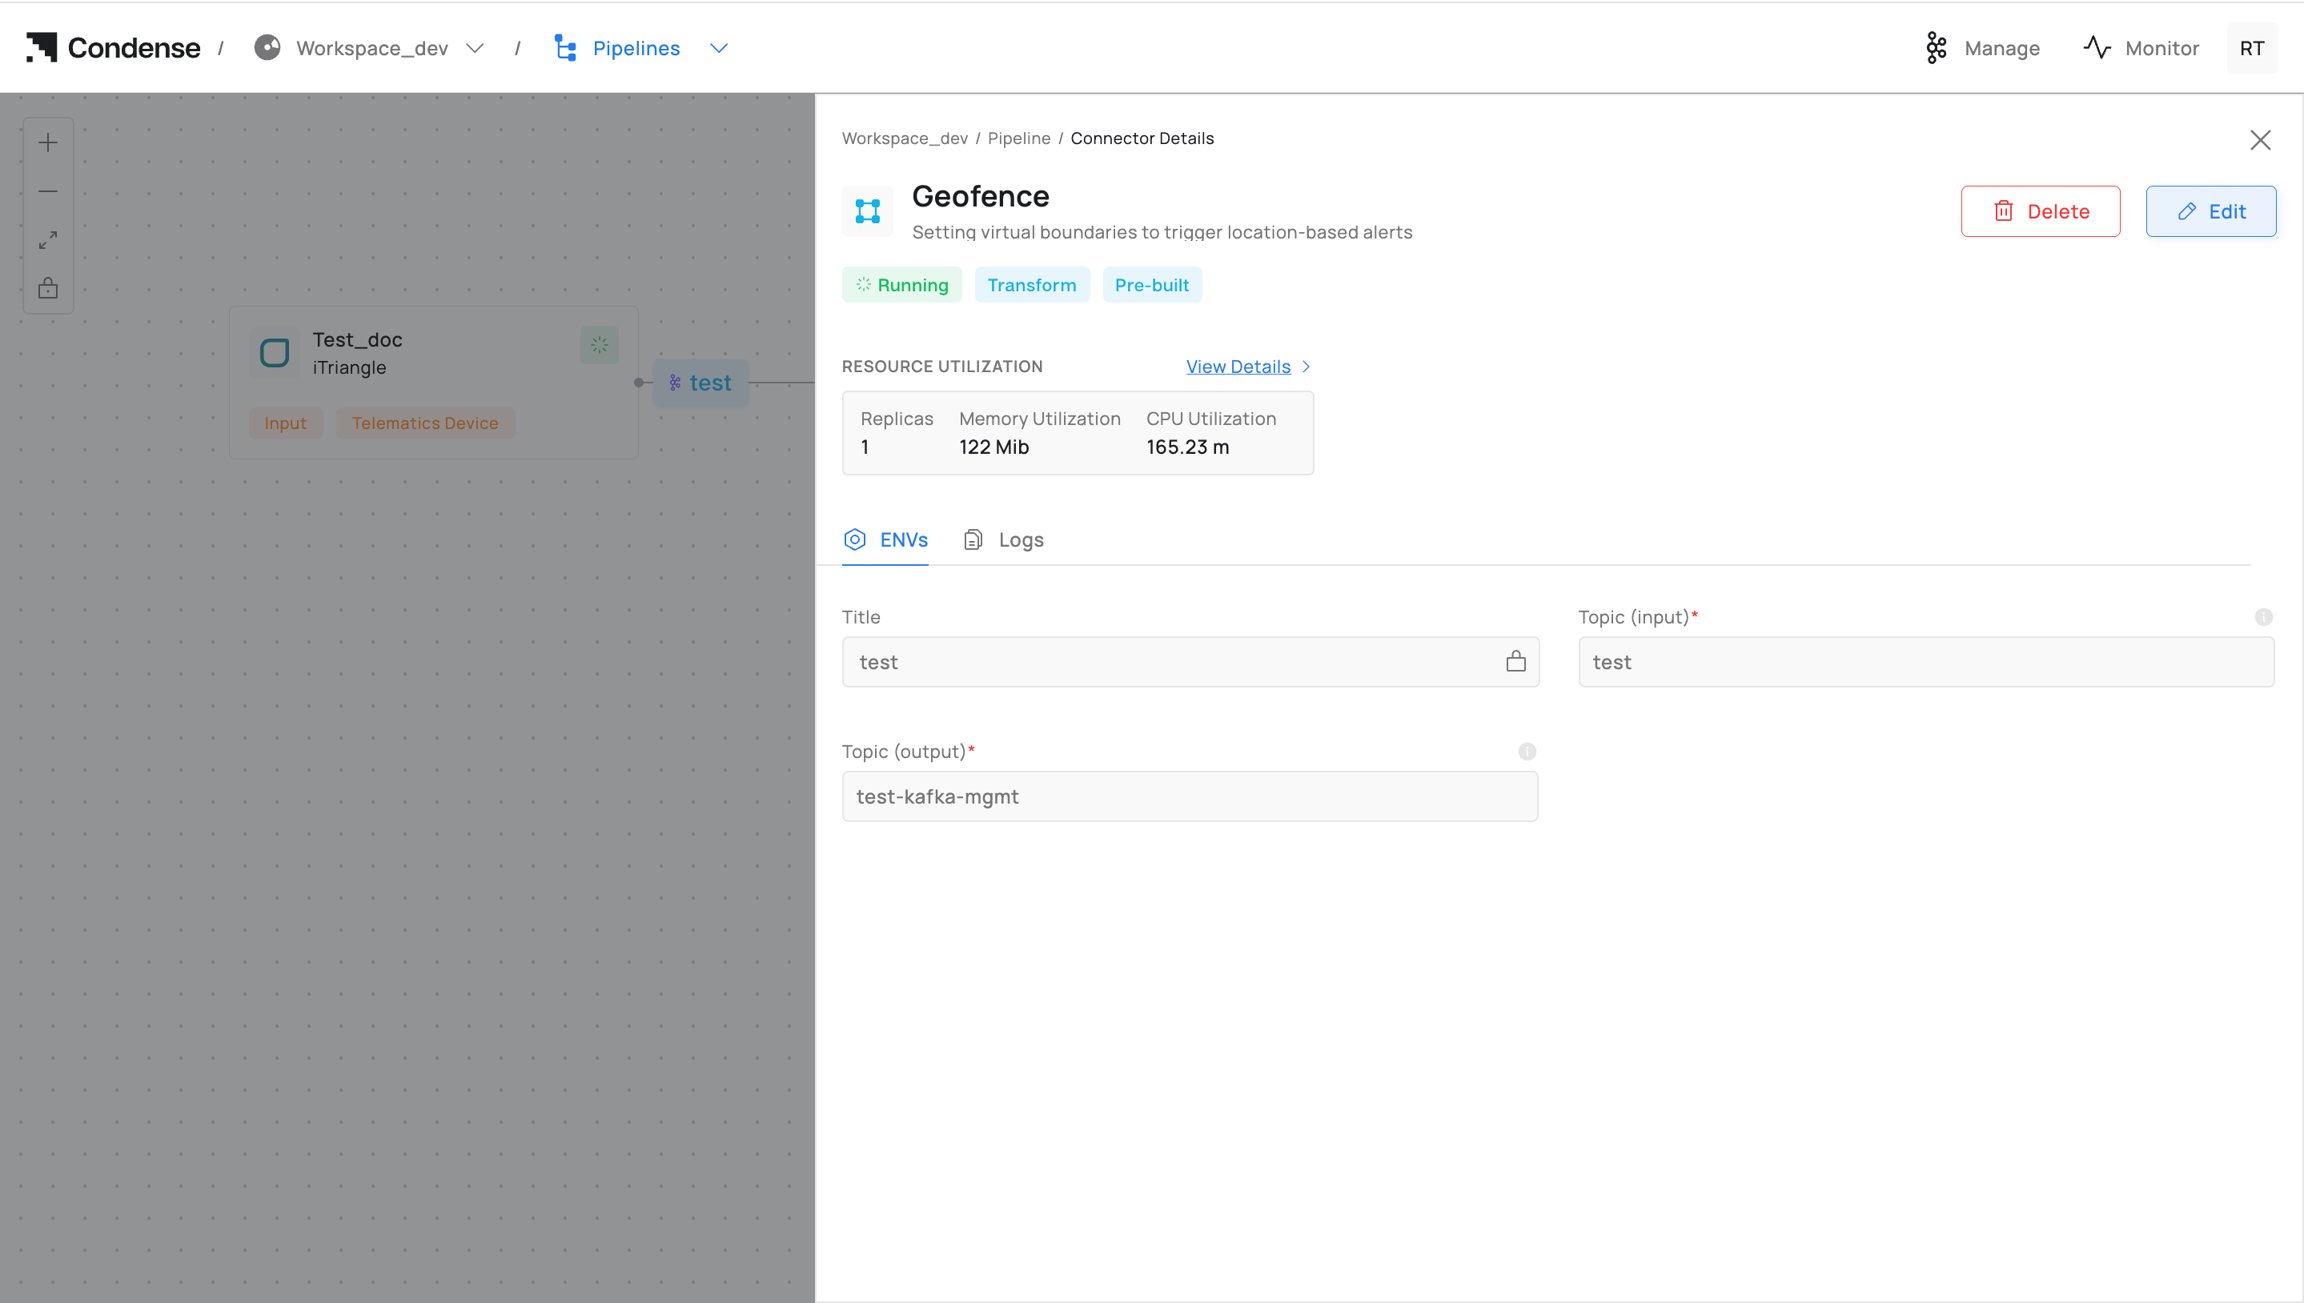
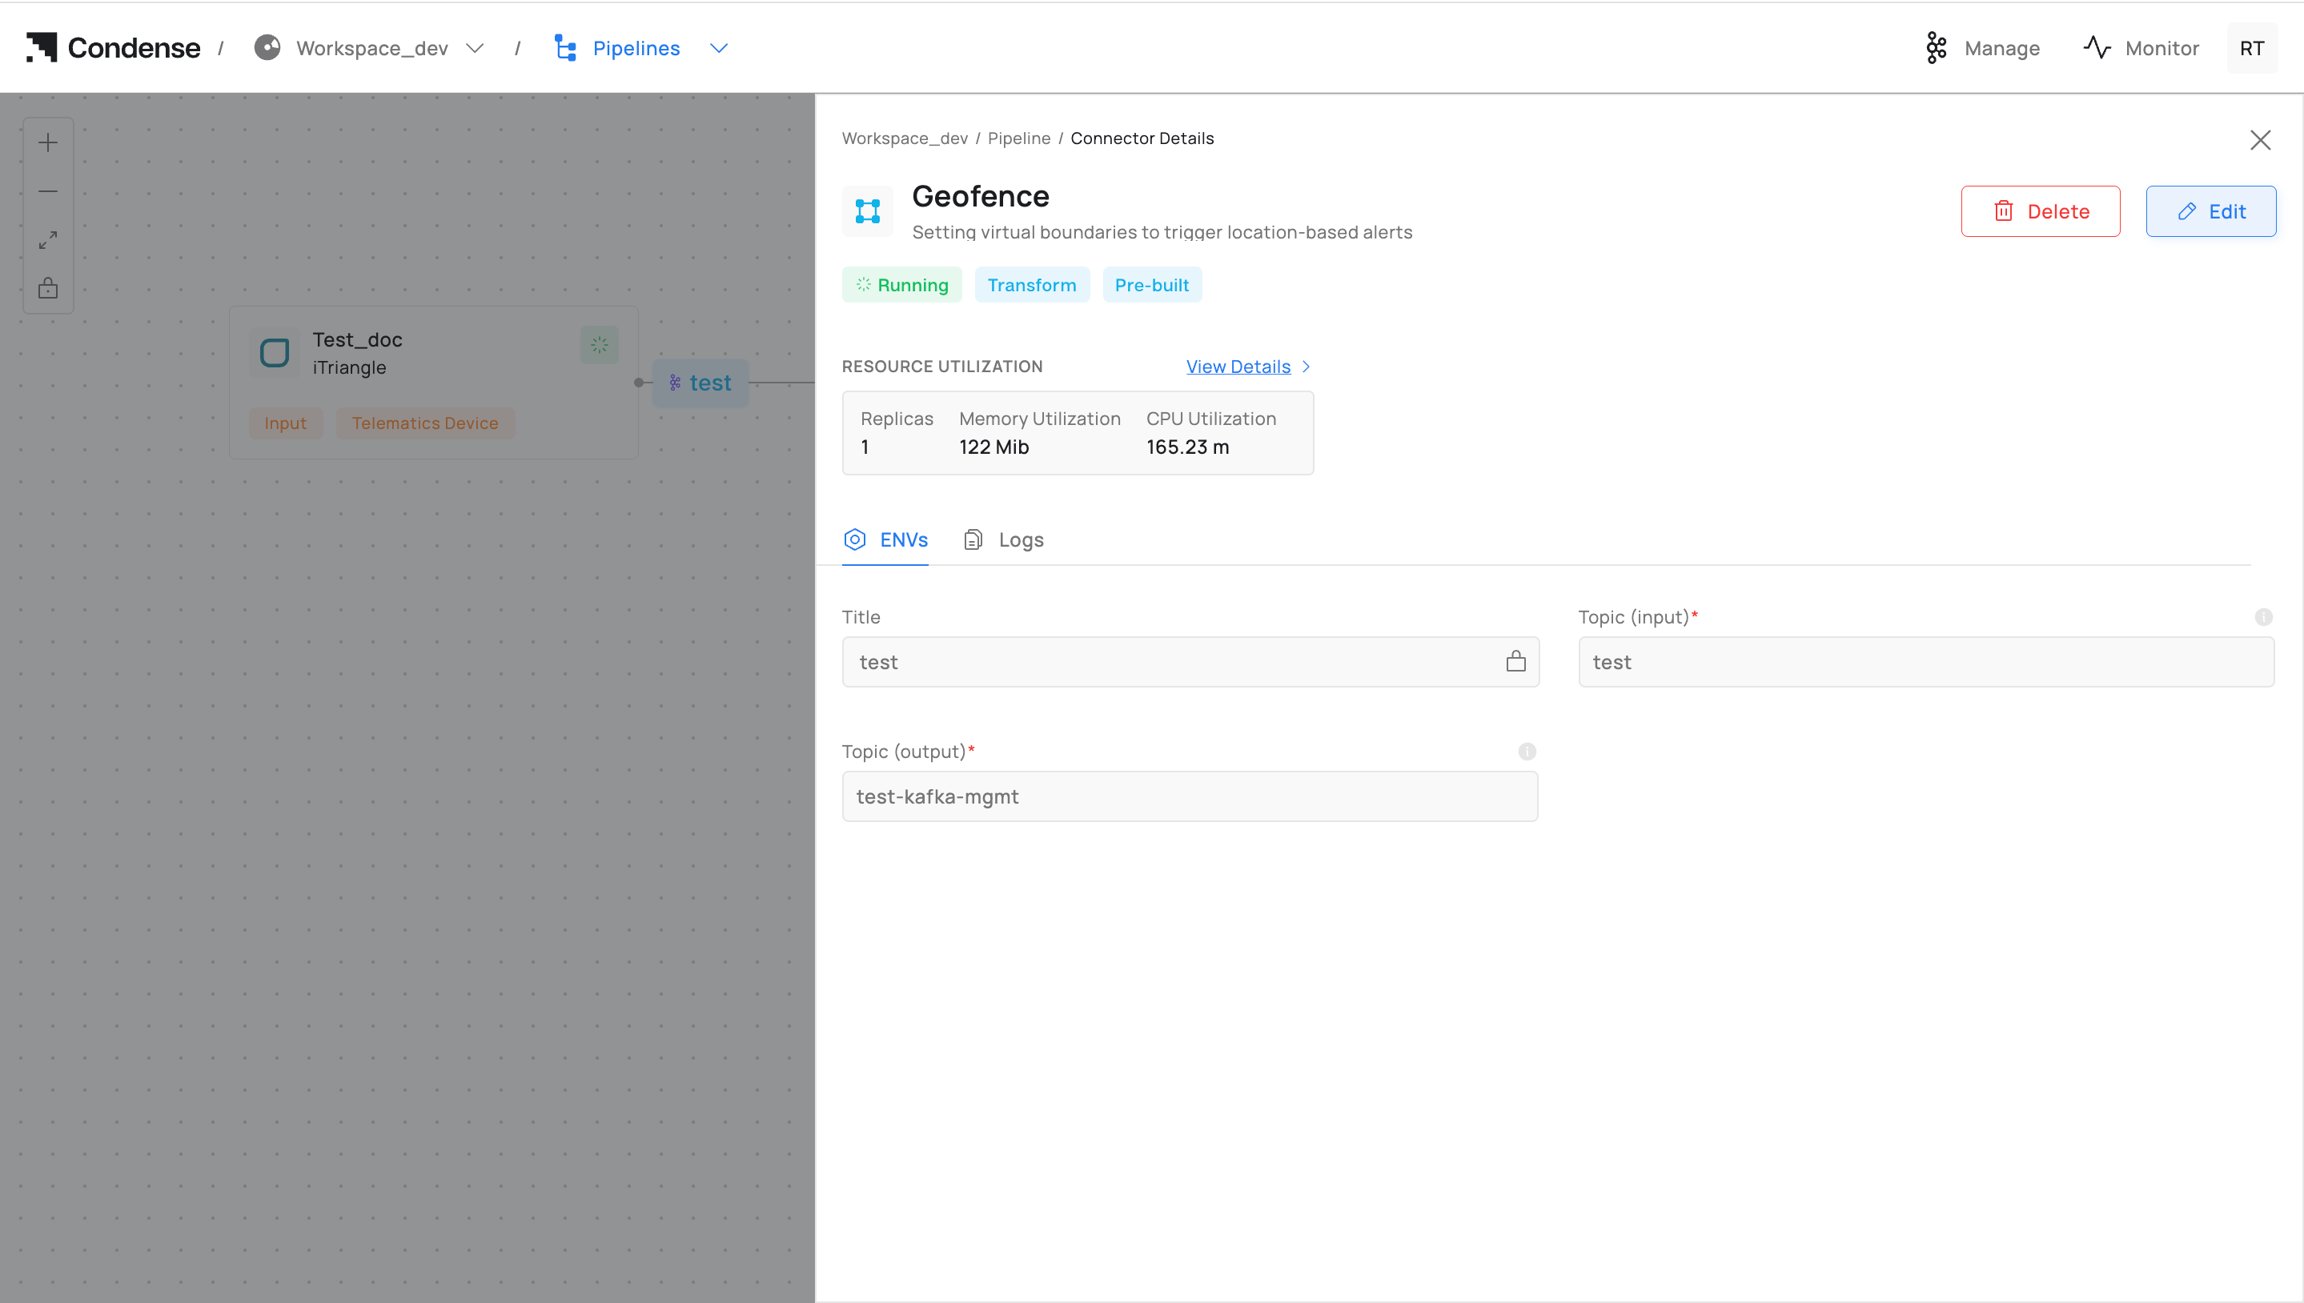
Edit Deployed Transform
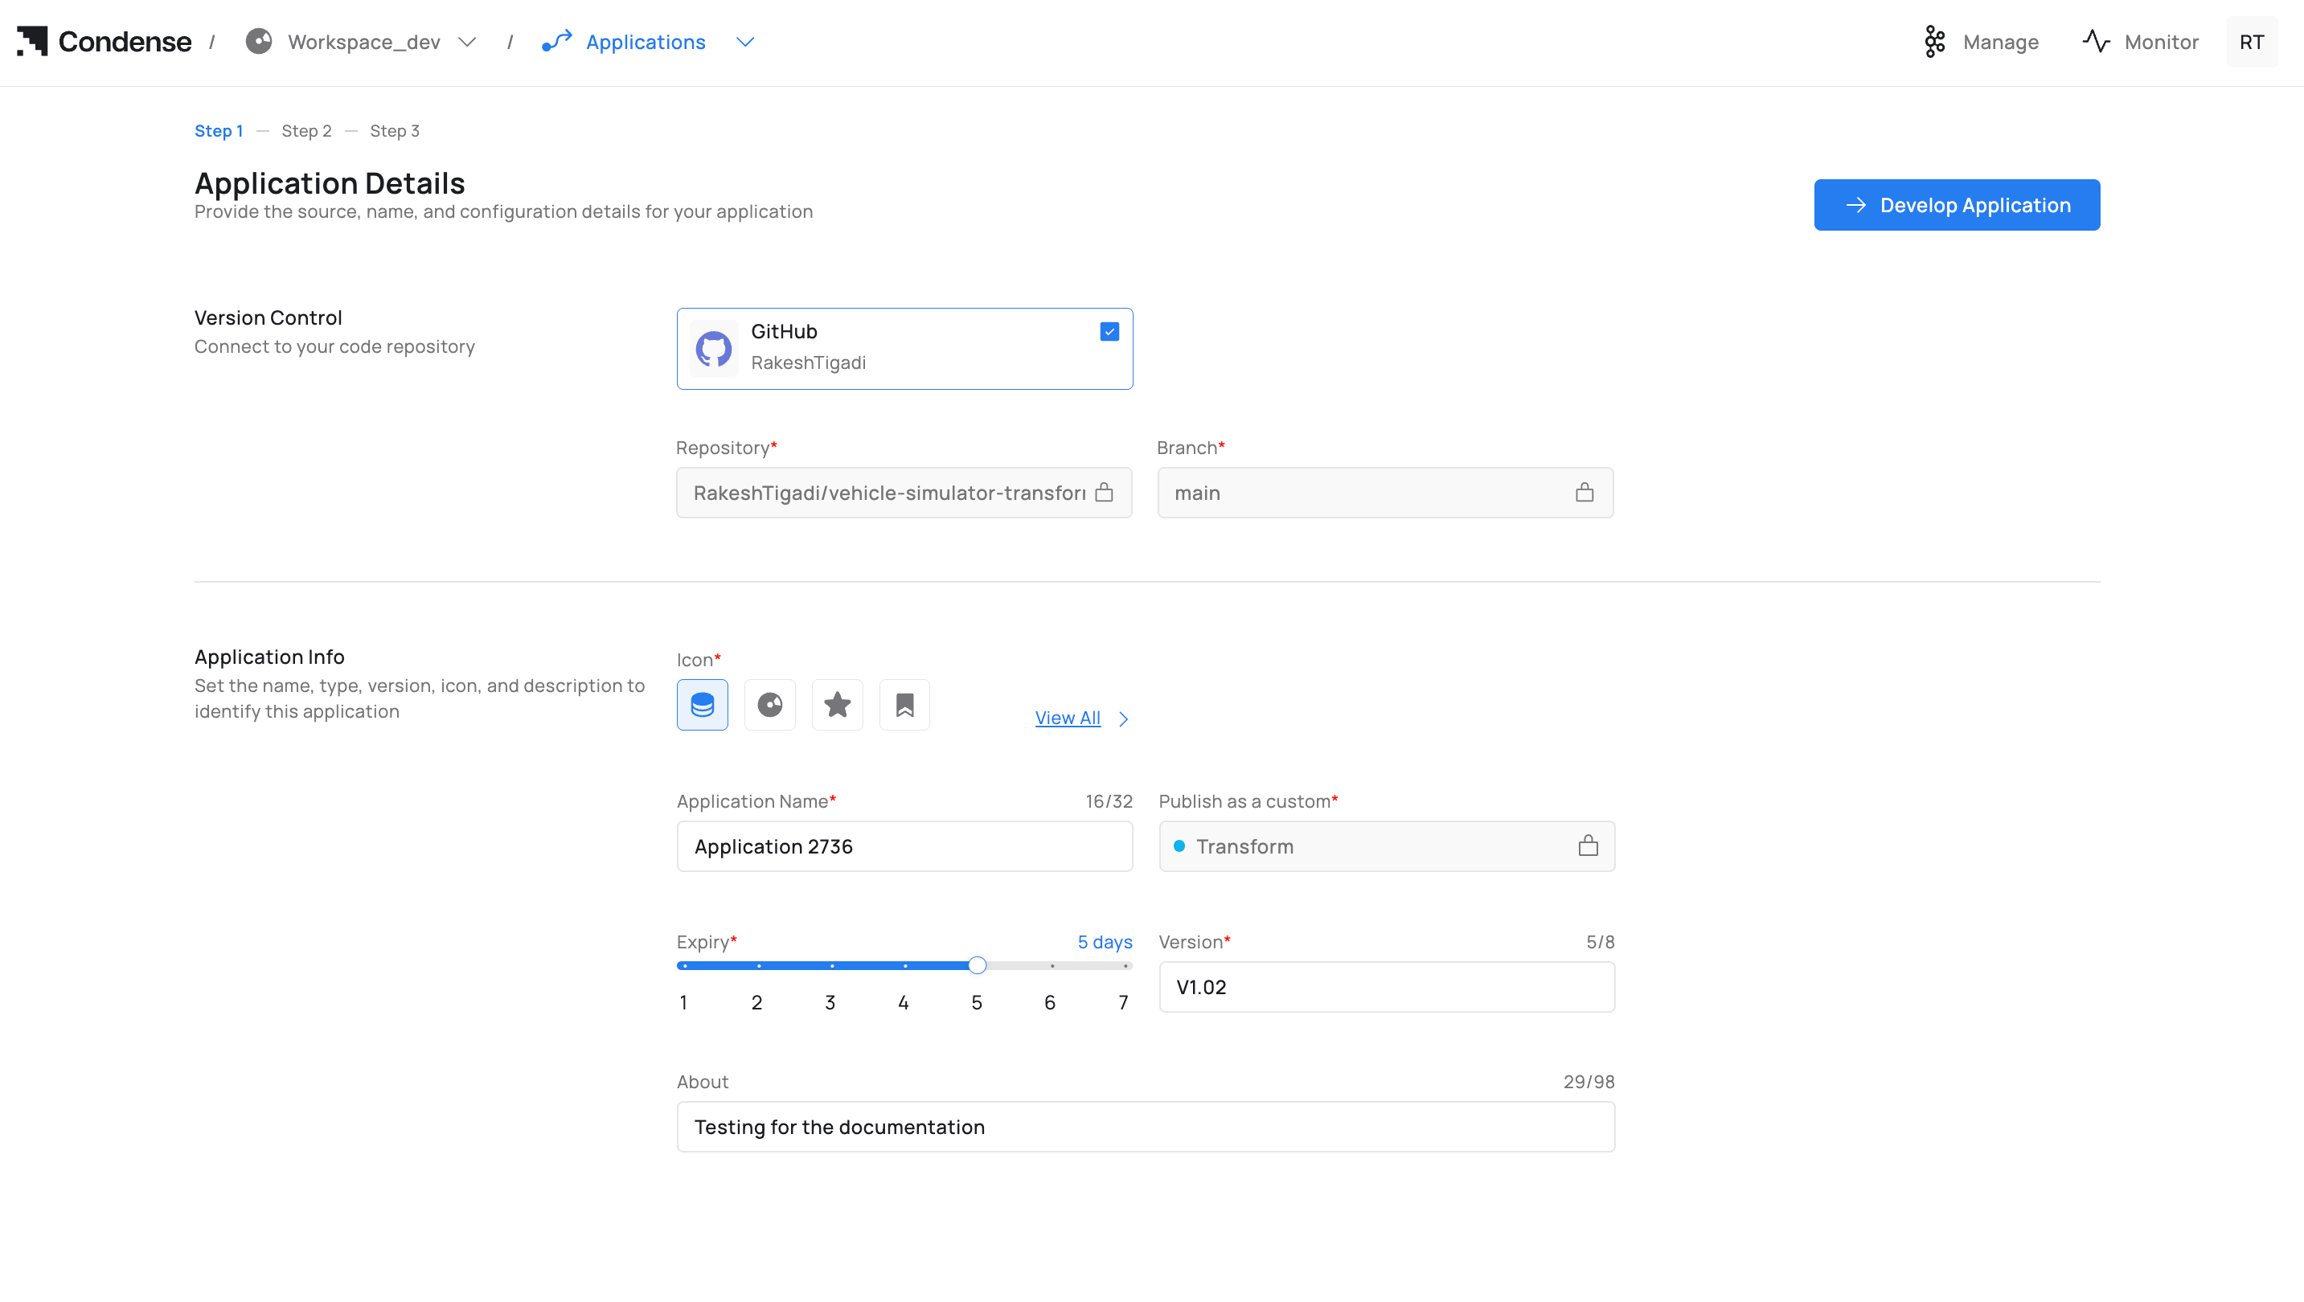
Adding a New Version
Roles and Permissions
Monitoring and Audit
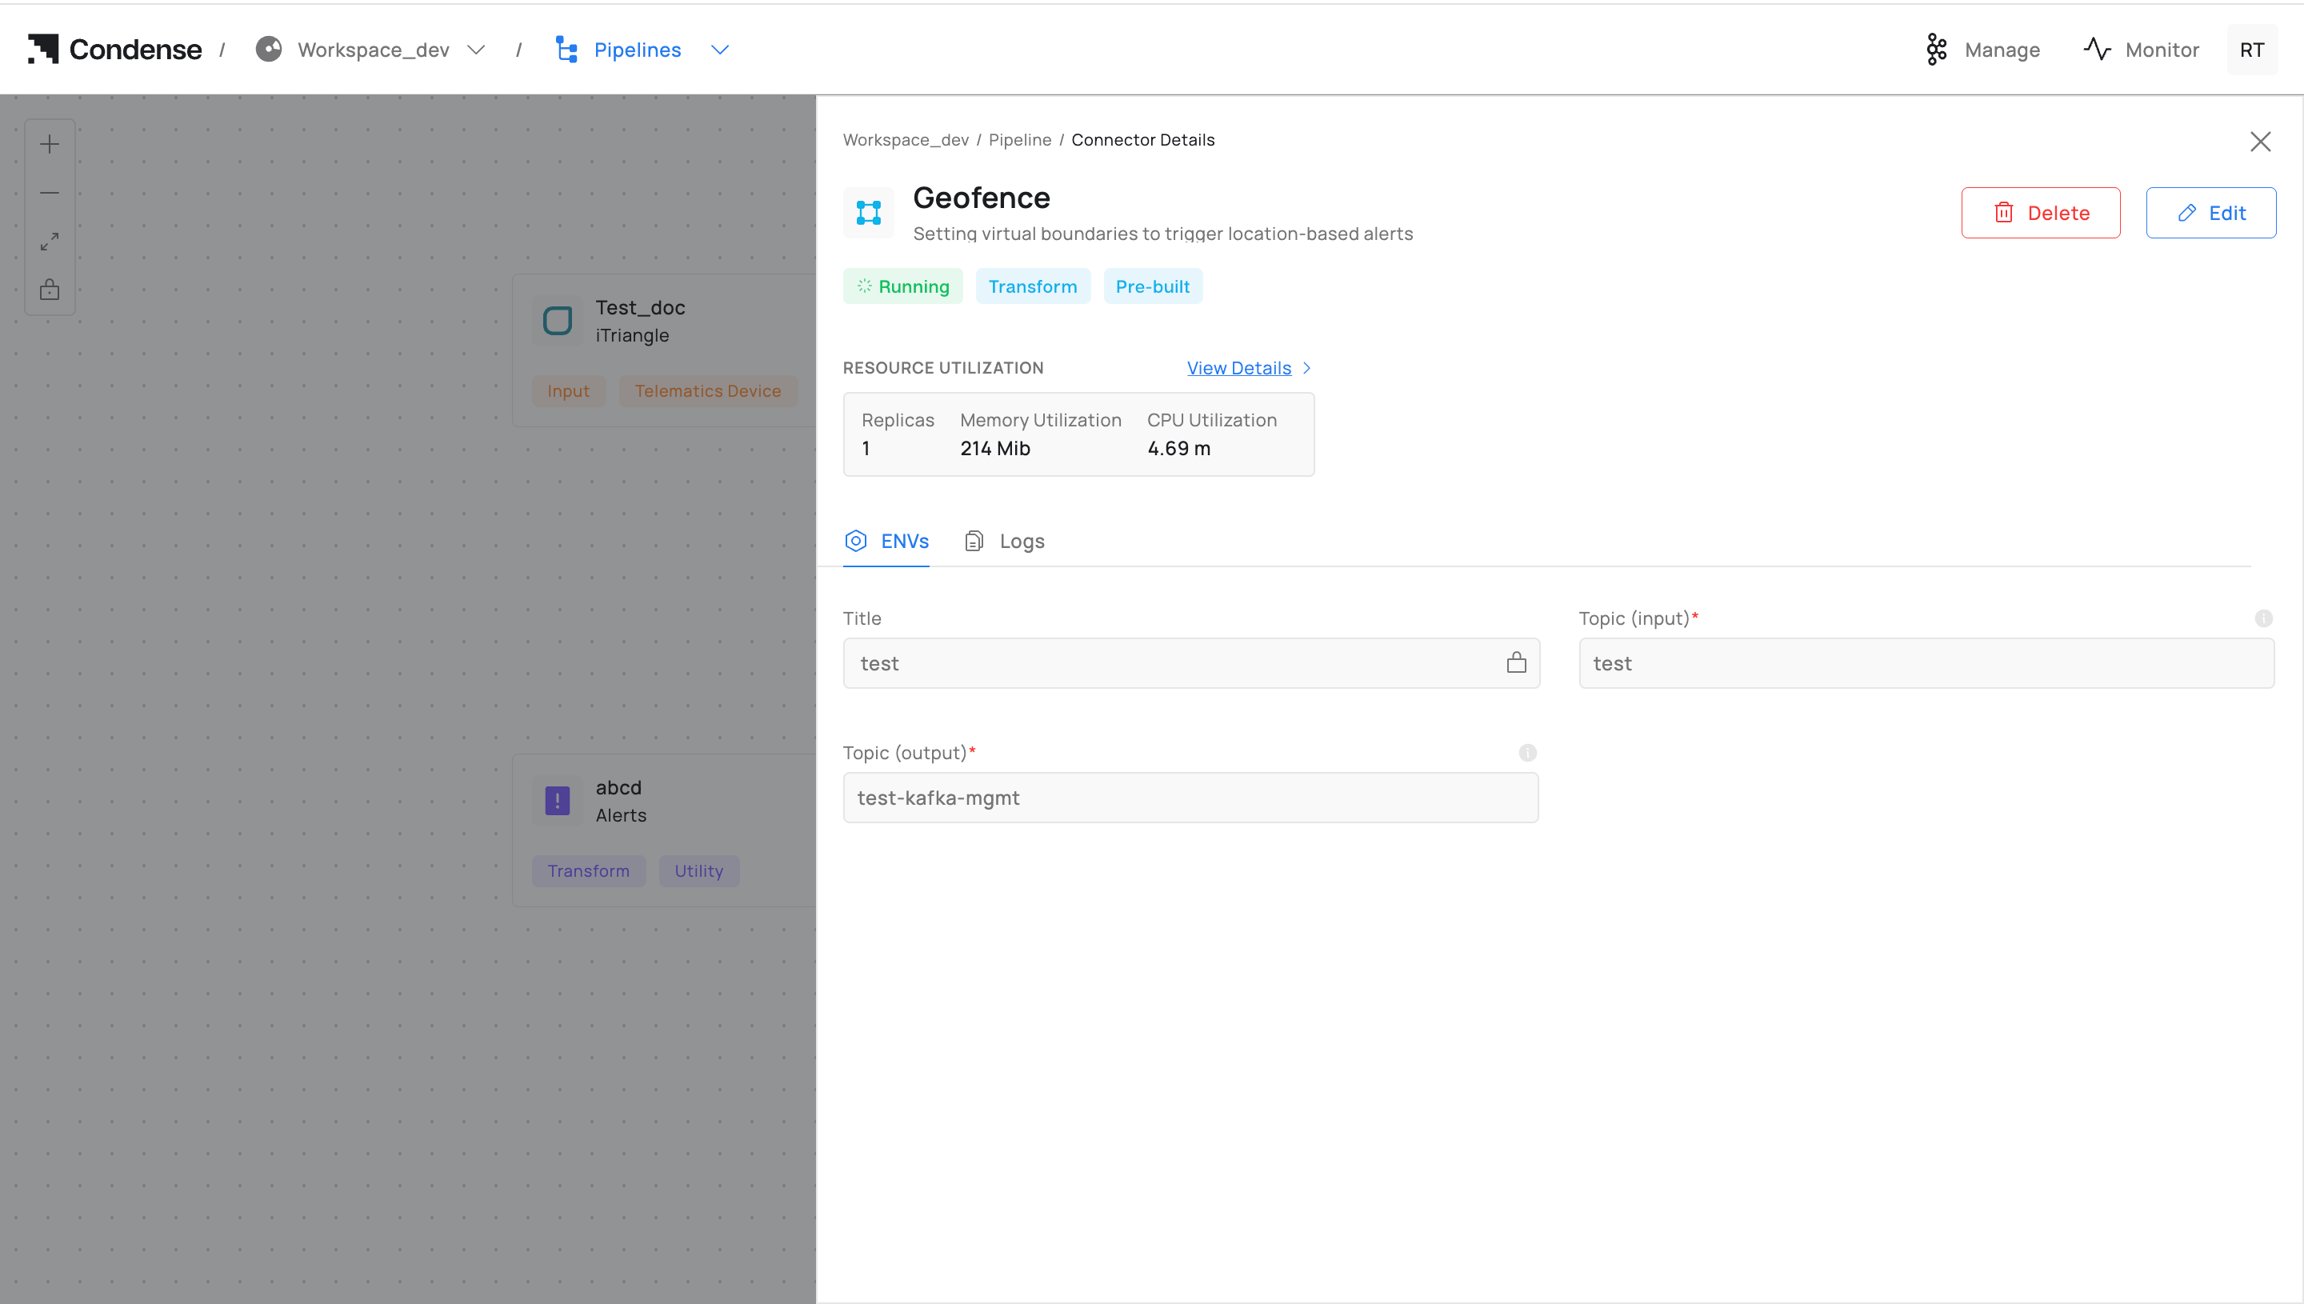
In the pipeline view, click on a deployed transform block to open its detail page. Here you can view:- Status (active, error)
- Execution metrics (throughput, processing latency, error rate)
- Resource utilization metrics
- Version history for each transform
- Activity logs for creation, modification, and deletion events
- Runtime logs (stdout/stderr) via the Logger/observability stack
Best Practices
- Keep each application focused on a single responsibility for simpler testing and review.
- Use ENVs over hardcoding - configure ports, credentials, and endpoints via environment variables.
- Map Git branches to deployment stages:
dev,staging,main. - Align Version labels, image tags, and Git tags/commits for full traceability.
- Always test using Publish/Subscribe testers before building.
- Keep custom transform logic modular and version-controlled in Git.
- Regularly review transform performance metrics to detect bottlenecks early.